yaadein

We set out to save stories. People told us it changed their conversations.

Then two people called us back the next day.

This is a case study for what happens after the recording stops. yaadein turns the craft of asking deep questions into four rungs, writes each next question from the last answer, and the proof we care about is not what people recorded — it is what they did an hour later, and a week later.

Custom capstone, 100xEngineers Cohort 7. Shefali Mody, Eddie Aditya Bhardwaj, Hansh Goyal, Munish Bhardwaj. Submitted October 7, 2026.

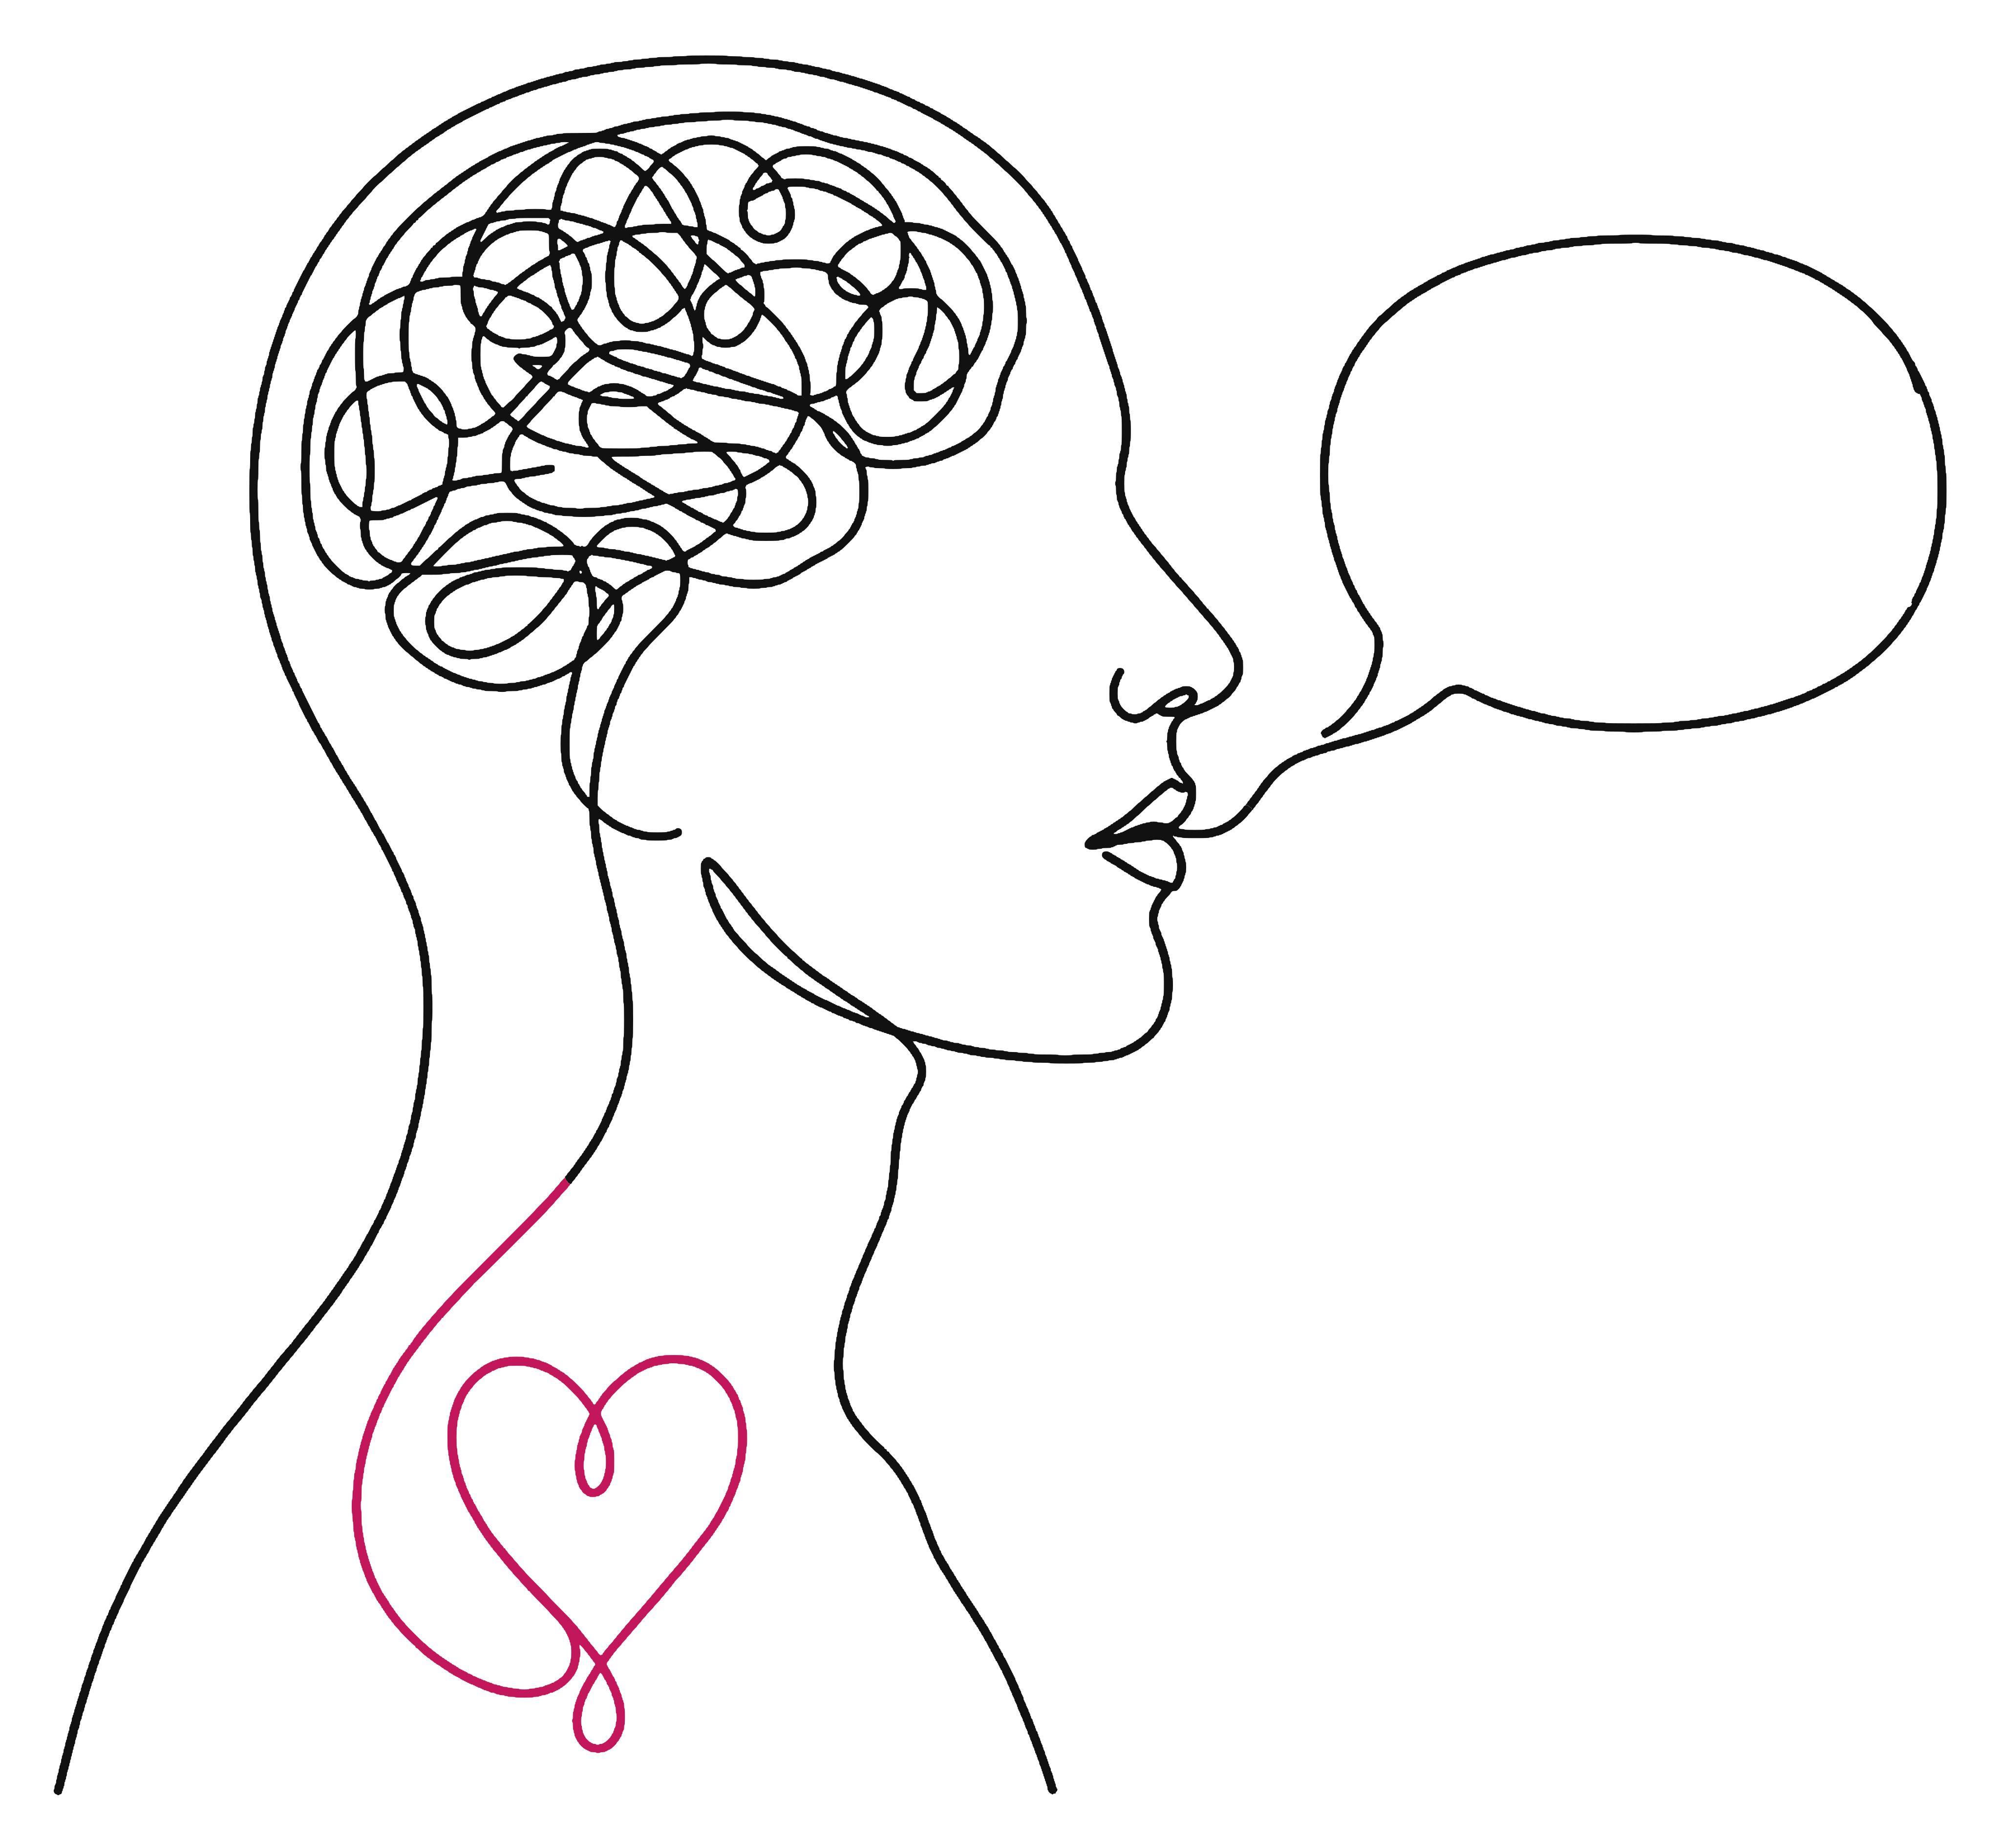
Line drawing of a person speaking the word yaadein, with the four rungs Yesteryears, Atmosphere, Afterword and Disclosure beside them, Disclosure level with the heart
Rung Y: 17 secondsRung A: 81 secondsRung A: 49 secondsRung D: 166 secondsRung Y: 42 secondsRung A: 31 secondsRung A: 59 secondsRung D: 64 secondsRung Y: 11 secondsRung A: 38 secondsRung A: 102 secondsRung D: 95 secondsRung Y: 24 secondsRung A: 98 secondsRung A: 102 secondsRung D: 151 secondsRung Y: 20 secondsRung A: 15 secondsRung A: 40 secondsRung D: 4 secondsRung Y: 4 secondsRung A: 51 secondsRung Y: 5 secondsRung A: 4 secondsRung Y: 8 secondsRung A: 86 secondsRung A: 144 secondsRung D: 353 secondsRung Y: 5 secondsRung A: 28 secondsRung A: 40 secondsRung D: 21 secondsRung Y: 4 secondsRung A: 14 secondsRung A: 17 secondsRung D: 17 secondsRung Y: 22 secondsRung A: 22 secondsRung A: 55 secondsRung D: 51 secondsRung Y: 3 secondsRung A: 3 secondsRung A: 17 secondsRung D: 9 secondsRung Y: 6 secondsRung Y: 4 secondsRung Y: 3 secondsRung A: 11 secondsRung A: 15 secondsRung Y: 24 secondsRung A: 52 secondsRung A: 115 secondsRung D: 55 secondsRung Y: 7 secondsRung A: 48 secondsRung Y: 12 secondsRung A: 16 secondsRung A: 14 secondsRung D: 39 secondsRung Y: 7 secondsRung A: 14 secondsRung A: 6 secondsRung D: 6 secondsRung Y: 6 secondsRung A: 7 secondsRung A: 21 secondsRung D: 13 secondsRung Y: 5 secondsRung A: 30 secondsRung A: 22 secondsRung D: 16 secondsRung Y: 47 secondsRung A: 78 secondsRung A: 35 secondsRung D: 82 secondsRung Y: 27 secondsRung A: 65 secondsRung A: 60 secondsRung D: 39 secondsRung Y: 1 secondsRung Y: 11 secondsRung A: 20 secondsRung A: 62 secondsRung D: 39 secondsRung Y: 4 secondsRung A: 18 secondsRung Y: 3 secondsRung Y: 8 secondsRung A: 13 secondsRung A: 15 secondsRung D: 11 secondsRung Y: 12 secondsRung A: 3 secondsRung A: 4 secondsRung D: 16 secondsRung Y: 9 secondsRung A: 23 secondsRung A: 8 secondsRung D: 61 secondsRung Y: 4 secondsRung A: 4 secondsRung A: 4 secondsRung D: 4 secondsRung Y: 6 secondsRung A: 6 secondsRung A: 7 secondsRung D: 7 secondsRung Y: 3 secondsRung A: 2 secondsRung A: 2 secondsRung D: 2 secondsRung Y: 8 secondsRung A: 4 secondsRung A: 5 secondsRung D: 2 secondsRung Y: 37 secondsRung A: 38 secondsRung A: 33 secondsRung D: 45 secondsRung Y: 17 secondsRung A: 17 secondsRung A: 18 secondsRung D: 23 secondsRung Y: 3 secondsRung Y: 6 secondsRung A: 21 secondsRung A: 34 secondsRung Y: 34 secondsRung A: 26 secondsRung A: 7 secondsRung D: 70 secondsRung Y: 17 secondsRung A: 29 secondsRung A: 37 secondsRung D: 43 secondsRung Y: 67 secondsRung A: 101 secondsRung A: 63 secondsRung D: 9 seconds

Every bar is one of the 139 answers recorded in Wave 2. Its height is how long the person talked.YAAD

What yaadein is, right now

Three ways in, same engine behind them all.

KeepsakeDESIGNED

A photo or video, a question, and the voice of why it matters. The on-ramp from an album to a memory.

See the design →
ReflectionLIVE

Answer the L1-L4 ladder about yourself. A solo warm-up before you send a question to someone else.

How it works →
TogetherLIVE

Ask someone you love, their answer in their voice, every next question built from the last one. The hero mode.

How it works →
THE GOLDEN RULE WE FOUND

Build on their own words. In Wave 1, the deepest question worked because it handed the person's own phrase back to them. Every rule in our engine protects that.

What we saw, before we built anything

Both of Shefali's parents are in memory care with advanced dementia. She grew up on the story of how they met, heard at the dinner table so often she could recite the beats. She has her version of that story. She will never have theirs.

That looked like a problem about dementia, or about running out of time. It isn't. Shefali is here and can speak, and nobody has ever asked her what it was actually like to grow up as an Indian migrant in Sydney and start again in America. Not because anyone is careless. Because when someone does ask, they ask "so what was it like?", and that question has no way in.

The bottleneck isn't time, storage, or the phone in your pocket. It's the question.

Restating the problem that way changed three things. The people we could test with stopped being only the elderly and became everybody. The barrier stopped being time and became a skill. And that skill turned out to belong to people who ask for a living, who can do it but can't tell you how.

What we believed, and what would prove us wrong

Our hypothesis changed twice, and the change is part of the story (see what changed). Where it stands now:

If an Asker uses questions built on a four-rung ladder, each written from the answer before it, the person answering will tell them something they have never heard before, and will talk longer the deeper the ladder goes.

What would prove it wrong

  • The ladder's questions produce no more new disclosure than the Asker's own questions on the same topic.
  • Answers don't lengthen as the rungs go deeper. If people talk just as long at the fact rung as the disclosure rung, the ladder isn't doing the work.
  • People who ask genuinely good questions still get one-sentence answers. Then the barrier is the subject, not the question.

The baseline

In our first manual run, the fourth and hardest answer ran 1 minute 25 seconds in total across two unaided conversations. With framework-built questions on the same topics, it ran 4:16 (questions written by Claude) and 3:22 (an expert interviewer).

Wave 2 ran the app-guided conversation only. We did not capture an unaided comparison in Wave 2, so our baseline remains Wave 1's hand-timed result. When we tried running the unaided conversation a few times, participants got confused between the two conversations and recorded on their phone's voice memo app instead of through ours, so nothing comparable was captured. Running the unaided conversation through the app is our next step.

Our approach

We treated yaadein as an experiment with software attached, not software with a survey attached.

Eight steps, in order. The two marked in solid pink are where real people used it without us steering.

1Observe
A lived problem, stated before any product.
2Hypothesize
A claim, and what would prove it wrong.
3Run it by hand
Wave 1: six conversations, no screen, no app.
4Let evidence redesign it
Keep what broke, change what it showed.
5Build the smallest instrument
The Mom Test app, to run more sessions.
6Run it with others
Wave 2: Askers who aren't on the team.
7Score from both sides
Surveys for both people, evaluators on the recordings.
8Report all of it
Including what failed.

Six rules we held ourselves to

Measure first, build second

The software is how we get to the measurement. We built only what the next test needed.

By hand before code

Wave 1 ran with no app at all, so we'd know what the app had to do before anyone wrote it.

Two people, not one

Both the Asker and the respondent are surveyed after every conversation, and the Asker's emotion counts as much as the respondent's.

Nobody performs for the score

Participants never see how we score. People who know emotion earns points may perform it.

The Asker stays in charge

A person always decides what gets asked. The model suggests; it never decides.

The diff is the deliverable

Every design change is traced to the evidence that caused it, including our own mistakes.

The ladder: four rungs, YAAD

Yaad is the root of yaadein, Hindi for memories. Each rung goes a little deeper, and costs the person answering a little more, than the one before. The first two are about the memory. The last two are about the person.

YYesteryearsThe plain recordWho could answerA strangerAAtmosphereWhat it was likeWho could answerSomeone who was thereAAfterwordWhat it meantWho could answerSomeone willing to thinkDDisclosureNever said aloudWho could answerOne person, to one otherone topic, going deepercost to the person answering
Each rung costs the person answering more than the one before. The thread stays on one topic the whole way down.

The app writes each next question from the last recorded answer. The Asker stays in charge: they can accept a question, reject it, or write their own. Off-limits topics can be set before the conversation starts.

What we ran

  1. Wave 1, by hand. Six recorded conversations across two threads, three rounds each: the Asker's own questions, Claude's, then an expert interviewer's. Nobody answering ever saw a screen.

  2. Redesign from the evidence. Expert round retired, two conversations on the same topic, nine measures defined with scales, surveys for both people after each conversation.

  3. Mentor working session. Live demo of the Mom Test app with our mentor as the respondent, and a steer to prioritize new disclosure, stay close to users, and not let the technology become the bottleneck.

  4. Wave 2, through the app. Askers and respondents recruited by the team and by referral, running the ladder through the Mom Test app, with every answer recorded, transcribed and timed.

How a session runs

Only two of the eight steps involve a model. Everything else is either a fixed rule or a person, and a person always decides what actually gets asked.

Step 1 · HThe Asker picks atopic and off-limitsStep 2 · PThe app writes onequestionStep 3 · HThe Asker asks it, orrejects itStep 4 · HThe respondentrecords an answerStep 5 · PThe answer istranscribed and timedStep 6 · DThe next rung isrequestedStep 7 · HBoth people fill in asurveyStep 8 · DEverything is loggedsteps 2 to 6 repeat for each rungDa fixed rulePa model, a judgment callHa person
A Wave 2 session in the Mom Test app. D is a fixed rule, P is a model making a judgment call, H is a person.
So what

The ladder is why conversations keep going.
2 of 13 · The Evidence

What we proved

61sessions logged
139recorded answers
27complete two-sided surveys
21/27shared something new, confirmed blind by two evaluators
17/27respondents wanted to ask back
2respondents reconnected with the person outside the app

"After the app closed, the conversations kept going."

Three waves, three months

How we got here, and where Wave 3 lands.

Wave 1 Sept 12 6 sessions, hand-timed Wave 2 Sept 23 – Oct 4 61 sessions, 139 answers Wave 3 · after demo day Nov onwards (target) 200 sessions · ripple scored blind
Each bar is sessions run. Wave 1 was six conversations with a stopwatch. Wave 2 was sixty-one through the Mom Test app, and is where this submission ends. Wave 3 begins after demo day — it is the first run with Insights live, and the first where we score the ripple blind.

What we measure

Nine measures, each with a written definition, a scale, and a named way of scoring it.

Four come from short surveys both people answer after each conversation. Two of those, Novel Disclosure and Insight Shift, were then checked blind: two evaluators listened to every recording without seeing the survey answers, and their calls matched the participants' in all 27 conversations, the yeses and the nos. Five more are scored by an evaluator from the transcript or the recording, with a second evaluator scoring blind. Answer length, the share of answers over 60 seconds, supports them but isn't one of them: Wave 1 showed that a long answer and a meaningful one aren't the same thing.

Survey, confirmed blind by two evaluators

Novel Disclosure

Our headline. Did the respondent share something they had never told anyone, or never told this Asker? A memory that didn't exist until someone asked.

Yes / No, asked of both so neither grades alone
21 of 27, from both sides; evaluators agreed on every answer
Survey, confirmed blind by two evaluators

Insight Shift

Did the conversation change how you understand the moment, and how you see the person?

Yes / No: two questions for the Asker, one for the respondent
22 and 20 of 27 (Asker), 22 of 27 (respondent); evaluators agreed on every answer
Evaluator, from the transcript

Disclosure Landing Rate

Did the conversation reach the fourth rung, and did the respondent give a real answer to it?

Reached, and answered: yes / no
30 of 41 reached rung 4; answers being scored
Evaluator, per question

Question Rating

Did each question stay on the subject, go exactly one rung deeper, and build on something they'd just said?

1 off track · 2 on topic, not deeper · 3 built on their answer
Evaluator scoring underway
Evaluator, from the recording

Response Depth Score

Did the answer produce audible emotion from either person? A pause, a sigh, a laugh, a voice breaking. Joy counts as much as sadness.

0 none · 1 moderate · 2 strong, scored blind by two people
22 Askers and 17 respondents of 27 noticed emotion (survey)
Evaluator, plus survey

Reciprocity

Did the respondent ask the Asker a question back, about the topic or the Asker's own life? Logistics don't count.

Yes / No
17 of 27 wanted to (survey)
Evaluator, from the transcript

Willingness Gap

Did the respondent engage, decline with a reason, or deflect? A considered no is never a deflection.

Count of deflected answers
Evaluator scoring underway
Survey, both people

Keepsake Value

A year from now, would you play this recording again?

1 probably not · 2 maybe once · 3 yes, I'd go back to it
12 Askers and 14 respondents of 27 said 3
In-app, counted automatically

Return Rate

How many times a user actually comes back to replay a yaadein. Watched-again proves the keepsake was worth keeping.

Replays per memory, per user, per month
Measured in-product from Wave 3 onwards
Survey + in-app, Wave 3 onwards

Ripple KPI

After using yaadein, has your connection with the person you asked actually increased? Over time we intend to measure this directly — the metric will present itself with clarity once we collect more data in months 6–9.

Self-reported connection change · outside-app contact within a week
Baseline from Wave 3; clarity by month 9
Survey, both people

Waitlist Intent

Would you like to join the waitlist for the yaadein app?

Yes / No
23 Askers and 22 respondents of 27

Deferred until after this build: Self-Awareness, a validated dual-rater quiz we'll need for the future "asking yourself" memories.

What we found

Wave 1: the framework beat improvisation

Six hand-timed conversations, two threads, three rounds each. At the disclosure rung, the Asker's own questions held people for 1 minute 25 seconds in total. Framework-built questions held them two to three times longer, whoever wrote them.

0:001:002:003:004:000:360:49Unaidedboth threads: 1:250:154:01Claudeboth threads: 4:161:551:27Expertboth threads: 3:22Thread 1Thread 2
Seconds the respondent talked at the disclosure rung, Wave 1. We don't claim Claude beat the expert: the two threads disagree about that.

Timed rung by rung, the shape is clearer. Neither unaided round goes deeper: both peak early and fade before the disclosure rung. Three of the four assisted rounds build to their longest answer there.

Thread 10:001:002:003:004:00YAADThread 2YAADUnaided (the Asker's own questions)ClaudeExpert
Seconds talked at each rung, Wave 1. The one assisted round that fell away (Claude, thread 1) opened with a question so good it spent the round's energy on the first rung.

Wave 2 at a glance

105sessions logged by the app84real sessions, after removing 21 tests61two-person conversations (23 were reflections)41with at least one recorded answer30went all four rungs deep
Wave 2 sessions through the Mom Test app, September 23 to October 4, 2026. Reflections (someone asking themselves) are counted on their own below, not in the conversation figures.
139recorded answers73.4minutes of answers39people21 of 41answered sessions with a team member in them5:53longest single answer

New disclosure, from both sides

Twenty-seven conversations have complete surveys from both the Asker and the respondent. Reflections, a mode we added on September 30 where someone answers the ladder alone, are reported separately: 14 of 23 got at least one answer, 44 answers in all, 10 reaching rung 4. They have no second person to survey, so they sit outside the figures below.

AskerRespondentHeard something new /shared something never told21 of 2721 of 27Changed how they see the person /the moment20 of 2722 of 27Noticed emotion22 of 2717 of 27Wanted to ask the Asker a question backn/a17 of 27Would play it again in a year (top score)12 of 2714 of 27Asked to join the waitlist23 of 2722 of 27
Twenty-seven conversations with complete surveys from both people. The dashed row is the honesty check: how many would genuinely replay the recording.

Every figure in this chart comes from the participants' own surveys. "Noticed emotion" counts anyone who rated it moderate or strong.

Checked blind. For new disclosure and insight, we didn't take the surveys on trust. Two evaluators listened to all 27 recordings independently, before seeing anyone's survey answers, and judged whether a new disclosure and an insight had happened. Their calls matched the participants' in every conversation, including every one where people said nothing new came up.

Results hold without our professional testers. Five participants are professional testers: executives who ask questions for a living. Four of them used the app. Three appear in our figures, in 9 of the 61 conversations and 5 of the 27 surveys; the fourth answered after our data cut-off. We kept them in, because each was a real conversation with a real person in their life. Take them out and the results hold: new disclosure 17 and 19 of 22 (Asker, respondent), and insight 18, 17 and 19 of 22.

The deeper the rung, the longer people talked

Median length of answer at each rung, and the share of answers that ran past 60 seconds.

How often Askers took the app's question

The app offered 161 first questions across the real conversations. Askers used 79 as written. Across all attempts, they rejected 130 questions and asked for another or wrote their own.

79 used as written82 rejected, rewritten, or the session ended
Each square is the first question the app offered at a rung, across the 61 real conversations.

Where sessions stalled

Before the first question is written, the Asker types the topic. How much they typed made a large difference.

Average answers recorded, out of fourFirst question rejectedOne to three words1.559%Four words or more2.628%The 20 conversations that never got an answer11 began with a topic of three words or fewer
How much the Asker typed as the topic, before the first question was written.

One full ladder, start to finish

What the engine produces in practice. Four rungs, anonymised, consent cleared. The Asker is a daughter; the respondent is her father; the topic is their old house in Pune.

Open the transcript
L1 · Facts

Q: What street was the old house on?

A: "Prabhat Road. Number 14. Second lane."

L2 · Experience

Q: When you turned off Prabhat Road into the second lane, what did it sound like?

A: "Cycle bells. Neighbour's radio. Marathi news at seven."

L3 · Meaning

Q: Looking back, what did that quiet second lane give you that you didn't notice at the time?

A: "Room to think. I didn't know I needed it until years later."

L4 · Exposure

Q: What do you understand now about needing that room to think that you could not have understood back then?

A: "That the quiet was raising me. I thought I was just waiting for life to start."

Each question is built from the keyword in the answer before it. Line 2 picks up "second lane". Line 3 picks up "quiet". Line 4 picks up "room to think". That is the engine. Everything else — the guardrails, the rejection loop, the evaluators — exists to make sure the chain never breaks.

What we didn't expect: the ripple

We set out to help people ask better questions and keep the answers. Then people started telling us something we hadn't designed for and weren't measuring: the questions were changing their relationships.

OUR HYPOTHESIS HASN'T CHANGED

A written ladder still has to beat asking on your own, and not everyone has a big moment. Most answers are simply good stories. This section is a discovery, not a new claim.

Two things people told us afterward

CHAIN OF EVIDENCE

The ripple is not just two self-reports. We have a dated voicemail from Shefali to the team on Oct 2 — "Maureen just called her sister for the first time in six months" — and session Z8T2J shows Bruno asking a question back inside the app the same evening his wife finished theirs. Both events are timestamped and logged. Wave 3 scales this from anecdote to measure.

Why this might be happening

Daniel Goleman describes emotional intelligence in four domains: self-awareness, self-management, social awareness and relationship management. Without planning to, the ladder seems to touch three of them. Answering a deep question makes you notice something about yourself. Asking one makes you notice something new about a person you thought you knew. And, sometimes, people act on it.

RECOGNITION REGULATION SELF SOCIAL SELF-AWARENESS Emotional Self-Awareness Accurate Self-Assessment Self-Confidence SOCIAL AWARENESS Empathy Organisational Awareness Service Orientation SELF-MANAGEMENT Self-Control Transparency Adaptability Achievement Drive Initiative RELATIONSHIP MANAGEMENT Inspirational Leadership Developing Others Influence Change Catalyst Conflict Management Building Bonds Teamwork & Collaboration REFLECTION & KEEPSAKE REFLECTION & KEEPSAKE INCREASED CONNECTION
Goleman's Four Quadrants of Emotional Intelligence (2002), in yaadein colors. Reflection and Keepsake strengthen Self-Awareness and Self-Management; both feed Relationship Management, which we're labeling increased connection with the people you love.

The signals were already in our data. 17 of 27 respondents wanted to ask a question back, and our focus group's sharpest complaint was that the first version "felt one-way." What people wanted wasn't a better archive. It was a two-way conversation.

How we'll find out if it's real

Two stories are not evidence of an effect, and we won't pretend they are. In Wave 3 we measure it with two questions. An hour after answering, both people are asked whether anything new came up for them. A week later, the Asker is asked: did you contact this person outside yaadein? If the ripple is real, that number will show it.

What we're building because of it

The ripple is why the next version adds Insights: a private view for the Asker of their year in voices (who they heard from, how many answers, how long they listened) and how long they've been talking with each person, with a no-penalty pause for illness or time away. An hour after answering, both people are asked privately whether anything new came up, so the Wave 3 measure is built into the product (see the screens). Of the 30-plus products we reviewed (see who else is in this space), none shows the people asking anything about the relationship itself. They show the archive. Insights is how we give the ripple somewhere to go.

Mapped onto the EQ framework above: Reflection and Keepsake build the self side (self-awareness and self-management); Together and Insights carry that into the social side. The output we're measuring is Goleman's bottom-right quadrant, Relationship Management, which for yaadein means increased connection with the friends and family you love.

Insights closes the loop. Tracking each user's own KPIs — people heard from, hours listened, memories made — encourages the next conversation, which deepens connection and adds another memory, which raises the numbers again. It becomes a flywheel in its own right (see how the main flywheel turns).

Why people don't ask

We assumed one barrier. The interviews found at least three, and better questions only fix the first.

Better questions help

They don't know how

"So, what was it like?" gets a sentence, and families decide the other person "isn't a talker." This is the barrier the ladder is built for.

Better questions help

They're afraid of the answer

One Asker had four undistracted hours with her mother and still didn't ask the question she has carried for years. The ladder makes the hard question reachable in steps.

Questions can't fix this

They don't trust what happens to it

Another had shared something private and seen it used against her. That's a safety and privacy problem, which is why respondents can decline and set off-limits topics.

Questions can't fix this

They think it's covered

People in their twenties told us they already have photos, stories and chat history. People in their thirties, forties and older were curious to try it.

What we measure next

Our hypothesis is about depth. The ripple is the discovery. Wave 3 measures both, and the ripple is the part we most want to know about.

The ripple: is it real?

1 hour

Both people, privately: did anything new come up for you? An insight, yes, something small, or not really. This check is already designed into the app.

1 week

The Asker: did you contact this person outside yaadein?

Ask back

Did the respondent actually send a question back, not just say they wanted to?

30 days

Did the same two people talk through yaadein again?

The hypothesis, measured properly

Same topic, twice

The Asker's own questions, then the app's, both recorded inside the app, so every session carries its own baseline.

Scored blind

New disclosure coded by evaluators from the recordings, not only self-reported.

By rung

Answer length and the share over 60 seconds at each rung, as supporting proof.

The right people

40 to 55

People in our target range using the app, not just reacting to it. In Wave 2, 19 of the 30 users who gave a birth year were in their twenties.

Letters of intent

Commitments, not survey intent, once the version with vetted threads and one spoken memory is in people's hands.

WHAT WOULD TELL US THE RIPPLE ISN'T REAL

If most people answer "not really" an hour later, and few Askers contact the person outside yaadein within a week, then the ripple was three good stories, not an effect. We'll report that as loudly as we'd report the opposite. Targets for each measure are in what's next.

So what

21 of 27 shared something new. Two called back. The engine works.

3 of 13 · Testimonials

What professionals said

Quotes from people who ask questions for a living — the kind who use yaadein's skill in their own workplace every day. Plus the two moments that most surprised us, and Maureen’s own voice.

Our five professional testers

Executives who ask questions for a living. Four used the app and one reviewed it. Each card links to their LinkedIn and to the sessions behind their words. Mike and Maureen, independently, praised the same thing: questions they didn't have to think of. Peter described the ladder and the ripple in his own words: simple first, then deeper, and a conversation that kept going after the app closed. Jane, who reviewed it, named the reason it matters: the voice is what you miss.

Used the app with his mom
Mike

Mike Weaver

CEO, Dream Weaver Entertainment

I just wanted to leave a review about yaadein and how instrumental it has been in helping my mom and I capture memories. … It's very important that we communicate and also ask great questions. This was just a really cool way for us to communicate, and also the system came up with great questions that we didn't have to think of. It was super intuitive, and we can keep them as memories forever.
View LinkedIn profile →
Session G32A5. Their answers came in after our data cut-off, so they are not in our figures.
LinkedIn →
Used the app
Once I did the first couple questions, I got the hang of it. And it was actually fun. … There was a question about my growing up in Trinidad. And with that question and the follow-up questions, it took me back to some beautiful memories. … My sister playing the tabla and I was doing Bharatanatyam. … I had not thought of that for a long time. … Down the road, my son can listen to it and know more things about me that I probably wouldn't even think of sharing at this point.

In her app feedback, as an Asker:

I like that the app provides questions based on the topic I choose, so I didn't have to think about questions to ask.
View LinkedIn profile →
Six conversations as Asker and respondent. The Trinidad memory is session 8URR7, with Shefali, on our team, asking. The feedback quote is from Z8T2J.
LinkedIn →
Used the app
Since it's new, there were a few technical challenges up front, but once we got it set up on my phone, it was very easy to use and the topics along with the generated questions started to flow. … Those memories from 12 years ago kind of got buried. These were small moments as opposed to the big ones in life. So not many pictures remain from that time. … Were we happy or sad about the time when I put way too much salt in my chicken curry? But we ate it anyway. … They would learn a lot more about us through the little moments along with the big ones.

In his app feedback, as a respondent:

… get to the emotional side of a particular moment instead of just the mechanics of the picture or video.
View LinkedIn profile →
In his early 60s. Two conversations with Maureen; the memory he describes is session Z8T2J, where the feedback quote also comes from.
LinkedIn →
Used the app with his wife
I like the way the questions are structured. They start off very simple and high level and then as you progress, they gradually become deeper and more personal. … What was even more interesting was the experience didn't really end when we finished using the app. … Me and my wife ended up having a conversation about some of those memories for quite a time after that. … In our day-to-day life we never had those kind of conversations. … It helped us as a couple relive those memories.
View LinkedIn profile →
Answered as a respondent, with his wife asking, sessions J8WFJ and GU2KV.
LinkedIn →
Reviewed the app and concept
My first reaction to yaadein was honestly amazement, but the kind of amazement that comes from joy. … I wish something like this had existed when we had her. I would have cherished the opportunity to capture her voice, her stories, the little things she remembered, and the way she told them. … Pictures are beautiful, but [there's something] incredibly special about being able to hear someone's voice and preserve their stories in a way that you can come back to. For me, yaadein isn't simply an app. It represents a way of holding on to the people we love in the moments we never want to forget.
View LinkedIn profile →
Did not run a session. In her 40s, inside our target group. She spoke about her grandmother.
LinkedIn →

Two moments we didn’t expect

A sister, after six months

Maureen recorded a memory of herself and her sister as children in Trinidad: her sister on the tabla, Maureen dancing Bharatanatyam. It brought her so much joy that she called her sister, for the first time in six months, and shared it. Her sister started crying. Before they hung up, they agreed to call each other every week.

Shared with her permission, from her own audio testimonial and from Shefali's voicemail to the team after Maureen called her

A husband and wife, for hours

Premal (Peter) Doshi, one of our professional testers, was asked to go one rung deeper into a memory he shares with his wife. Afterward they talked about it, and the memories linked to it, for several hours. Both said their everyday conversations had become about tasks, and this was the kind of talk they had stopped having.

Shared with his permission, from his voice message after his session (see his testimonial in the evidence)

In their own words

What was even more interesting was the experience didn't really end when we finished using the app. It went after that as well. Me and my wife ended up having a conversation about some of those memories for quite a time after that.Premal (Peter) Doshi, professional tester (see the evidence)
Maureen's audio testimonial, shared with permission.
So what

Five professionals. Five different reasons it worked.

4 of 13 · Demo Video

The demo

A short film the team shot to show yaadein in use.

So what

Watch sixty seconds. That is the whole thesis.

5 of 13 · What Broke

What Broke

Eleven things broke across both waves. Here they are in the order a session runs, with where each one stands.

1Setting the topic
Underway

Askers didn't know what to ask

19 of 61 Askers typed three words or fewer, like "Favorites." 9 of the 12 sessions that never got an answer began this way.

The blank box is our original problem, one step earlier. Fix: vetted threads to start from.

2Writing the question
Fixed

An opening question that was too good

Wave 1: a first question pulled two minutes out of someone, and every rung after it got shorter.

Fix: the first rung now asks for exactly one fact.

Fixed*

A question from the wrong point of view

In the live demo, a disclosure question was addressed to the Asker instead of the respondent. Our mentor caught it on the spot.

Fix: a direction rule in every prompt.

Fix drafted

Forced sensory questions

The atmosphere rung asked what water smelled like, on a topic with no smell. The cause was our own rule.

Fix: sensory only where the subject has senses.

Open

A question that accused

One Asker set the topic as a report and the relationship as "Enemy." The respondent, a professional tester, said she never wrote the report. The ladder built on the premise anyway, and the third rung asked: "Why did you claim responsibility for work you did not do?" This session still counts in our 41 answered and 30 fourth rungs.

Fix: redirect an "Enemy" relationship, check a named topic's premise at the first rung, and never build on an answer that rejects the premise. Session ZU2CU.

Due Oct 3

Formatting leaked into a question

One Asker saw a question with a markdown label still attached.

Fix: strip formatting before a question is shown.

3Recording and transcribing
Next step

The unaided conversation had nowhere to live

The app only captured the guided conversation. When we tried the unaided one, people recorded it on their phone's voice memo app instead.

Fix: the unaided conversation, inside the app.

Open

Hindi and mixed speech came back garbled

Some answers returned in the wrong script. In one session, a garbled word steered the next question onto the wrong person.

Lesson: a transcription error doesn't stay in the transcript. It steers the ladder.

4Measuring and exporting
Fixed

Our own arithmetic

Wave 1: timestamps were subtracted as decimals. 5 of 24 timings were unrecoverable, and two conclusions had to be corrected.

Fix: the app now times every answer.

Due Oct 5

A transcript lost to the spreadsheet

An answer ("January 2025," presumably) became a date on export.

Fix: transcripts exported as text.

5Safety
Open

A topic that needed more care

One session was about a person's current mental-health struggle, and the ladder went all four rungs deep.

Next: recognize live-crisis topics and step back.

Statuses as of September 29, 2026. *The point-of-view fix is in every prompt; Hansh is confirming the date it went live.

What changed, and why

Every change below came from evidence, not preference: what we believed going in, what we believe now, and what moved us.

We thoughtThe problem is dementia and running out of time
NowThe problem is that nobody asks properly
What moved us: Shefali realizing she can still speak and has never been asked either
We thoughtAn expert rules on each question, and the system learns her judgment
NowThe four-rung framework, applied by Claude, with the Asker in charge
What moved us: Wave 1: the framework beat improvisation whoever wrote the questions, and needing the expert present contradicted "anyone can ask"
We thoughtThree rounds: unaided, Claude, expert
NowTwo conversations on the same topic: unaided, then the app (in Wave 2, only the app conversation was captured)
What moved us: Wave 1 friction, and the expert round no longer tested our claim
We thoughtHeadline: share of answers over 60 seconds
NowHeadline: new disclosure, with answer length as supporting proof
What moved us: Wave 1 showed length and insight diverge: the longest answer changed nothing for the Asker
We thoughtOne barrier: people don't know how to ask
NowAt least three barriers, only one fixed by better questions
What moved us: Wave 1 interviews: fear of the answer, and broken trust
We thoughtThe Asker's reaction is secondary
NowEmotion from the Asker counts equally with the respondent's
What moved us: A yaad is made by two people, not extracted from one
We thoughtQuestion packs are worked examples for the model to learn from, never something Askers browse
NowAskers can start from a vetted thread, and each question after the first is still adapted to the last answer
What moved us: Wave 2: Askers who typed a one-to-three-word topic averaged 1.5 answers, against 2.6 for those who wrote a sentence
We thoughtManual sessions, run and timed by hand
NowThe Mom Test app records, transcribes and times every answer
What moved us: Wave 1's timing errors, and the need to run more sessions than four people could by hand

How the app got here: the build log

From the first commit to the submitted version, Sept 21 to Oct 7

This traces yaadein from the first commit (Sept 21, 2026) to main as of Oct 7, 2026 (a5e5080). It covers the product logic, not the code: at each milestone it records what wasn't working, what was missing, or what we wanted to improve, and what changed as a result. The source is the commit history and the reasons written into each commit.

What the whole cycle shows

Things we built, then took back. Each reversal came from real use, not a change of mind:

  • Listen gate: forced (day 1) → persisted (Sept 29) → removed (Oct 5).
  • Language: switch offered (Sept 24) → automatic (Sept 29) → fixed at start (Sept 30).
  • Primary model: Gemini → Claude → Gemini → Claude → Claude only. This was driven first by quota, then by latency, then by privacy.
  • Who can end a thread: the asker's third decline ended it → only the respondent can.
  • Names in prompts: removed for privacy → restored because the model lost who is who.

The product's center of gravity moved from "generate four questions" to "make a real conversation happen between two people, and capture it honestly". Along the way: hearing the answer, the respondent's right to say no, declined questions as data, consent, and then safety for the person being asked.

Friction was removed in layers: codes → links, typing → speaking, a role screen → a straight path, one-word topics → paragraphs → prompt packs, two people → Reflection.

Silent failures were the most dangerous bugs. Audio that never uploaded, transcripts rolled back by a type mismatch, a fallback chain that hid latency, a Groq cap that stranded people on round 2. Most fixes came with logging so the next one would be visible.

Milestone by milestone

Tap any milestone to open it.

0Starting point: a script and a ladder

The product began as mvp/yaadein.py, a terminal script. One person spoke an answer, local Whisper transcribed it, and Gemini (or a local Ollama model) wrote the next question. The core idea was already there: the L1–L4 ladder, four questions on one topic, each one deeper. Depth was defined by "what a question costs the person answering it":

  • L1 Yesteryears: facts a stranger could answer.
  • L2 Atmosphere: what it was actually like.
  • L3 Afterword: what they made of it.
  • L4 Disclosure: the thing never said out loud.

The first commit also ported this to a Next.js web app, with a two-person thread, a per-role KPI survey and a shareable transcript. It came with the Mom Test validation playbook, the evaluator guide and the scoring workbook. From day one, yaadein was a research instrument as much as a product: every session had to produce data for validating the idea.

1Making the two-person loop actually work

The web app's first version moved questions between two people, but the conversation didn't really happen.

What Broke What changed What improved
The respondent's recording never left their browser. The asker only saw the next question and never heard the answer. Answers stored server-side; the asker plays the clip (plus transcript) before the next question. Audio deleted after 24h. The asker actually hears their parent or friend. That is the point of the product.
Listening was optional, so an asker could skip to the next question unheard. Buttons lock until the clip has been played through. Scrubbing to the end doesn't count. Forced presence. (Reversed later, see §10.)
An asker could decline questions forever. Three options per rung. Declining the third ended the thread. A bounded session with a real cost to declining.
Gemini's free tier capped at 20 requests/day; Groq was rate-limited too. A busy day left no model. Claude added as a fallback, then made primary. Every provider attempt logged. Sessions stopped dying mid-thread, and failures became visible instead of showing up only as the fallback running out.
2Turning sessions into research data

The validation run needed clean, analyzable data and an experience a stranger could follow without help.

Who is speaking. Neither person's details were collected. Both now give age, occupation, email and phone before starting. Age soon became birth year because age goes stale, gender was added with "prefer not to say", and the phone field's +1/+91-only limit turned away everyone else, so it opened up.

Jargon. "I'm the asker / I'm the respondent" meant nothing to someone opening a friend's link. It became "Are you asking the questions, or answering them?"

Reciprocity. Asking the respondent to type a question to ask back was awkward. It became a role swap: at the end, "swap and start again?", with the form prefilled and names reversed.

Framework language. The rung labels were rewritten from Yesteryears/Atmosphere/Afterword/Disclosure to FACTS / EXPERIENCE / MEANING / EXPOSURE, with clearer per-rung guidance.

The most valuable data was being thrown away. Declined questions were overwritten in memory the moment a replacement arrived. The Mom Test scoring sheet calls the declined substitute its most valuable column. Every option is now logged with its outcome (Rejected, Accepted, Answered) and the model that wrote it. First this was one cell, which was unreadable, so it became one column per attempt.

The respondent had no way to say no. Their only action was to record, so declining meant recording themselves saying no, which looked like an answer. The playbook promised them the choice, and the Willingness Gap KPI is defined on it. The respondent can now decline, and the asker keeps authority over what gets asked aloud.

Ethics and exposure. A consent gate went in front of everything (declining collects nothing). The L1–L4 labels were hidden from the UI and replaced by "Question N of 4", because showing them handed the method to anyone who tried the app.

Readability. The survey sheet hit 99 columns, so KPI answers moved to their own tab in the layout the owner built by hand.

3Question quality: prompt engine v2

The questions themselves were the weak point, especially the deepest rung, which sounded the same in every thread.

The validated "Round B" framework came back into the engine with a new set of guardrails. The asker can also write their own question.

Two operational assumptions broke on the same day:

  • Audio wasn't reaching Drive. The upload ran client-side and only fired once both people had finished the survey, and most people closed the tab before that. Audio now uploads server-side, per answer.
  • "A session is one sitting" was wrong. People ran many conversations and lost any thread they left. Askers can now resume by code, and session lifetime went from 2h to 24h.
4From a spreadsheet to a real system

Redis plus Google Sheets worked, but people re-entered their details every time, consent was per session, and nobody could find their past threads.

  • Supabase became the database (normalized tables, row-level security). Written alongside the old system first, then read from.
  • Google sign-in, with consent recorded once per account and an "About you" profile filled in once. Deep links survive the sign-in round trip.
  • Thread ownership: only the owner can resume. A security gap closed along the way: draft data (rejectedThisRung) had been leaking to every polling client.
  • Sheets became an export, pulled from Supabase, rather than the source of truth.

The end-to-end test found silent data loss: a float duration written into an integer column rolled back the whole answer write, so transcripts vanished while the row still looked populated.

5Better input, less friction

One-word topics made flat conversations. People typed a single word, and the framework had nothing to work with. The topic became a paragraph field, and the prompt was told to read all of it. Neither half works alone. The caption was reworded twice because "not a topic word, the whole thing" read as a scold; it ended up as "the more you give us, the deeper we can go". Speech-to-text followed, because typing a paragraph on a phone is real friction.

Codes were friction. Invite links (/j/CODE, shared over WhatsApp) replaced typing a code. The code stayed as a fallback for phone calls.

The listen gate felt broken. A reload re-locked the buttons, and the hint was small gray text. Heard state now persists, and the hint became a visible notice.

Latency was hidden. Groq "answered in 300ms" while ~30s had already gone on Gemini 503 retries. Full timing was logged, which showed the problem, and Claude Opus 5.5 went back to primary.

A survey question made no sense. "Did this change how you see that moment?" asked about a moment the respondent was never told about. It was reworded.

Background knowledge. Optional web search on the topic now feeds the prompt, with names masked and results that name either person dropped.

Rules lived everywhere. Guardrails were scattered across prompt text, code comments and chat. guardrails.md and evaluators.md became the source of truth.

6yaadein without a second person: Reflection

The two-person format needs two people available at once, which is a big barrier. Reflection is a solo mode: you answer the L1–L4 ladder about yourself, and you decline by speaking.

The home screen reshaped around two paths. The two-person button went Find a respondent → Conversation → Interview → Together. "Conversation" implied two-way talk, when each person plays one role. Because sessions were now handed over by link, Together starts directly as the asker and the "asking or answering?" screen was dropped. The copy everywhere began promising "4 questions". The survey asks waitlist intent before open feedback.

7Hindi, and a reversal on language switching

Hindi support covers every screen, the survey, the share message and the model's questions.

The automatic language switch was removed. It had evolved in two steps: on Sept 24 it was an offer to the asker, and on Sept 29 it became automatic, because the next question was being generated in the old language before the asker could reply. With Hindi it was taken out entirely. The session language is fixed at start, with a regression test that catches a silent switch.

Whisper guessed every clip on its own. One Hindi session was transcribed as Norwegian Nynorsk, then Urdu, Urdu, then Hindi. The model copied the script, and the L4 question came back in Urdu. Whisper is now told the session's language, Hindi prompts require Devanagari, and a Hindi question containing Arabic script is rewritten.

Reliability failures surfaced alongside this:

  • The Groq fallback refused every rung from 2 on. Without an output cap it hit Groq's per-minute token limit (429), which left no provider. The person saw "couldn't save your answer" and was stuck on round 2.
  • Empty recordings produced the same generic error instead of "record again".
  • The shared transcript page leaked the session code through audio paths, and the code alone unlocks the audio.
8Giving the asker real choice over questions

The player looked broken. The native audio control showed endless buffering, because browser recordings have no duration header. It was rebuilt: the clip is fetched once, with a big play button, a brand progress bar and a visible Try again.

"Ask something else" threw questions away. Each decline overwrote the previous option. All three are now kept. The asker can go back to any of them, the model is told which question was actually asked, and the asker can no longer end the thread: only the respondent passing on all three can. The first UI, 1|2|3 tabs, confused people. It became a replay button that steps through the options.

Prompt packs. Not everyone knows what to ask about. Askers (and Reflection users) can pick a ready-made thread whose L1 question is asked exactly as written, with no model call.

9Python backend

Why: the backend logic was in TypeScript, which the owner couldn't easily read (the migration spec's stated goal: "so the codebase is readable to the owner"). The UI, the API contract and the database didn't change.

The port was proven in phases against the live TS (prompts and evaluators, then the session engine, then I/O, then routes), served to a cookie-gated slice, then cut over completely. Production logs right after the cutover showed Gemini's API key would have been written to them (httpx logs request URLs, and Gemini puts the key in the URL). Logging was silenced before any key leaked.

10Polish and another reversal

The listen gate was removed. Added on day one and persisted on Sept 29, it was a frontend-only lock the API never enforced. The asker can now move on without hearing the whole answer.

The end-of-thread button now goes home, so people choose Together or Reflection again. The player shows a waveform. Together's summary gained audio, as Reflection already had. The brand settled on lowercase yaadein in Bodoni Moda (a Baskervville trial was rolled back). The landing copy became the product thesis: "Most stories go untold because nobody asks the right questions. yaadein breaks the craft of asking into four simple steps, each one going deeper than the last."

11Safety and privacy

The product reads questions aloud to family members, often elderly parents, and records intimate answers. Until now, nothing checked either side.

  • Only Claude writes questions now. The fallback models also received every name and transcript, and a question Claude declined could be retried on them. Another model stays only for transcription.
  • Personal details are masked before they go anywhere. Spoken details that could identify someone had been stored as transcribed. Masking now runs before anything else sees the answer.
  • Topic search was leaking. The topic could still carry identifying details to a third-party search. That path was closed.
  • Prompt injection. A spoken instruction could be read as a command. What people say is now treated as data.
  • Every question is screened for harmful content. The screen never flags grief or trauma, which are the point of the conversation.
  • A reversal inside the same release. An earlier change had degraded Hindi questions; the fix restored them.
12Measuring question quality

The guardrails list rules but don't score output. Golden input→output pairs (50: L1–L3 ×10, L4 ×20 across the angles, including Hindi) give the evaluators a reference for what a good question and a good answer look like. This is the move from "the question follows the rules" to "the question is good".

So what

The engine learns in public. Nothing is hidden.

6 of 13 · The Interface

How our app evolved

MVP 1 is a web-based app

Four versions in three weeks, each one shaped by what the last one got wrong.

Every version since September 23 is a web app: people open a link in their phone's browser, with nothing to download or install.

Sept 12: a Wave 1 question being written in Claude, with names blurred

By hand, in a chat window

Each question written in Claude, copied out, and read aloud by the Asker. The respondent never saw a screen.

Why it changed: respondents waited 38 to 88 seconds between questions, and we timed answers by hand.

Sept 21: Pick a side. Two buttons and nothing else: I’m the asker, or I’m the respondent.

Pick a side

Two buttons and nothing else: I’m the asker, or I’m the respondent.

Sept 22: Plainer words. The buttons now say what each person does: asking the questions, or answering them.

Plainer words

The buttons now say what each person does: asking the questions, or answering them.

Sept 22: Setting up a thread. The Asker names both people, the relationship, one topic and anything off-limits.

Setting up a thread

The Asker names both people, the relationship, one topic and anything off-limits.

Sept 22: About you. Age, occupation, email and phone added, so the survey afterward reaches the right person.

About you

Age, occupation, email and phone added, so the survey afterward reaches the right person.

Sept 23: Brand color. Black buttons give way to the yaadein rose.

Brand color

Black buttons give way to the yaadein rose.

Sept 23: Join with a code. The respondent types a code from the Asker to join the thread.

Join with a code

The respondent types a code from the Asker to join the thread.

Sept 24: Consent before anything. What we keep and why, off-limits is absolute, and you can change your mind at any time.

Consent before anything

What we keep and why, off-limits is absolute, and you can change your mind at any time.

Sept 27: Google sign-in. One button replaces the code people had to find and type.

Google sign-in

One button replaces the code people had to find and type.

Sept 29: A line about what it is. “Someone you love. The right questions. A memory you’ve never heard before.”

A line about what it is

“Someone you love. The right questions. A memory you’ve never heard before.”

Sept 30: Description rewritten. Four carefully chosen questions, from someone you love or from within yourself, now that Reflection is live.

Description rewritten

Four carefully chosen questions, from someone you love or from within yourself, now that Reflection is live.

Oct 1: English or Hindi. A language toggle on the first screen.

English or Hindi

A language toggle on the first screen.

Oct 1: The same screen in Hindi. Every word on the page switches, including the sign-in button.

The same screen in Hindi

Every word on the page switches, including the sign-in button.

Oct 5: Brand fonts. The lowercase yaadein wordmark and the branding kit’s typefaces.

Brand fonts

The lowercase yaadein wordmark and the branding kit’s typefaces.

The interface

MVP 1 is a web-based app

For MVP 1, yaadein runs in the phone's browser. Every screen below is designed for a phone, and none needs a download.

WORK IN PROGRESS

The Pathways prototype below is not the final UI. It's a working design we'll keep reviewing and improving against user research over the next 6 months. Expect copy, flows and screens to change.

For the next version of the interface — redesigned around the ripple, five pathways and 53 screens — see The Interface Beyond the Demo Day under the What's Next tab.

So what

Every screen here was redrawn after a real session broke it. The interface is a logbook of what people actually did, not what we hoped they would.

7 of 13 · Evals and Guardrails

Golden rules and guardrails

A model writes the questions. These are the rules that keep it honest, kind, and on the right side of the conversation.

THE GOLDEN RULE WE FOUND

Build on their own words. In Wave 1, the deepest question worked because it handed the person's own phrase back to them. Every rule below protects that.

The guardrails run in three layers, from instant and cheap to careful and slower. Each one exists because we watched something go wrong.

Layer 1

Rule checks, in code

Instant and free. A question that fails is quietly rewritten before the Asker ever sees it, up to twice.

  • One question. Exactly one question mark, and at the first rung, no two asks joined by "and".
  • One breath. Short enough to say aloud without stopping.
  • Right direction. The Asker's name never appears, and the question never opens by naming the respondent.
  • No stock phrases. Phrases that make a deep question sound canned are blocked.
  • Anchored. From the second rung on, the question must reuse something from the last answer.
  • No repeats. A question can't go back over what an earlier rung covered.
Layer 2

A second model, checking the first

Built, and switched off for now. It exists mainly for off-limits topics: only a model can tell that a question about someone's marriage falls under "personal life." A keyword list can't.

  • Single ask, right rung, on topic
  • Right direction, off-limits respected
  • Builds on the last answer
  • At the deepest rung, invites and never corners
Layer 3

Session guardrails

Rules for the whole conversation, not just one question.

  • Junk answers. Under 15 words or 8 seconds pauses the next question, so a test or a glitch can't steer the ladder.
  • Language is chosen, never switched. "That answer came back in Hindi. Would you like the rest in Hindi?"
  • A consent beat before the deepest rung. "This one goes deep. You can skip it." Stopping there is a normal ending, not a failure.
  • A version on every question. Every question records the prompt version it came from, so results are compared fairly.
  • Adults only. Age is asked before anyone records, and under-18s are stopped.

Where each guardrail fires in the flow

One question moves through seven points. A guardrail is attached to the point where it can still change the outcome.

  1. Session start. Language locked (English or Hindi, never auto-switched: G5–G8). Profile validated (V1–V5). Topic web-search runs only if explicitly enabled, with names masked before and after the query (K: W1–W17). Claude is the only provider; no silent fallback (M1–M4).
  2. Model drafts the question. Prompt carries the shape rules (A: one question, one breath, plain language), direction (B: Asker speaks, no names in the question), depth (C: four rungs in order, L4 invites and never corners, no re-asking an earlier rung), and language script (G13 for Hindi: Devanagari only, never Urdu script).
  3. Code post-checks the draft. Script check (G14), name check (D2), banned-phrase check (P1, 15 phrases), moderation screen by Claude Haiku (N1). A fail triggers a silent rewrite, up to 2 retries (P2). After the last retry: shown anyway and logged (P3), except moderation, which never ships flagged (N2 → 502).
  4. Shown to the Asker. Only the question line is rendered; the rung and rationale lines are stripped (Q7). Owner-gated endpoints keep the drafts and raw replies off the respondent's device (R8).
  5. Rejection loop. At most three options per round (R1). Asker can write their own only after three exist (R4), capped at 300 chars, moderation-screened (N3). Thread ends only when the respondent passes all three (R2). A replacement never drops a rung and never rephrases a declined draft (L6, L7).
  6. Respondent answers. Audio must have bytes and speech (X11). Transcript is PII-masked in one pass before Redis, Claude, Supabase, or the Sheet see it: pattern layer for emails, IDs, 8+-digit runs, Aadhaar, spoken digit strings in English and Hindi (PII1); years, money, dates kept (PII2); birth days masked only in a born/जन्म window (PII3); addresses only when an address word is present, span-checked against the raw text (PII4–PII7).
  7. Session rules across the whole thread. Junk answers (under 15 words or 8 seconds) pause the ladder. Consent beat before rung 4. Every question stamped with PROMPT_VERSION. Adults only. Sessions, profiles and audio expire after 24 hours; share tokens after 7 days (X6).

Example drafts the guardrails caught

Each pair shows what the model wrote first and what shipped after the rewrite loop. Taken from the rules in guardrails/guardrails.md.

PII1 · Pattern layer on the transcript, before anything else sees it.

Raw: "Call me on nine eight seven six five four three two one zero, or priya.r@gmail.com."

Stored and sent to the model: "Call me on [phone], or [email]."

N3 · Asker's own typed question is screened too.

Typed by the Asker: an insulting or sexual question aimed at the respondent.

Response: 400 errors.questionBlocked. Nothing saved, nothing shown to the respondent, Asker sees the reason under the options.

Security

  • Encrypted in storage and in transit. Answers are protected wherever they're kept and whenever they move.
  • Not end-to-end sealed, and we say so. The model has to read each answer to write the next question, so answers can't be sealed the way a messaging app seals a chat.
  • Personal details masked before they are stored or reach the model. Live since October 7.
  • No participant data in our code. No keys, audio, transcripts or personal details anywhere in the repository.
  • Consent before anything is shown. No quote, clip or voice leaves the app without the person's agreement.

Behind all of it sit the safety lines described below: adults only for now, off-limits topics, the right to decline, and stepping back from live-crisis topics.

Evaluators

Done · merged into the app on October 7

The guardrails check that a question follows the rules. They can't tell you whether it's a good question. So we wrote down what good looks like.

We built a golden set: worked examples that show, rung by rung, the question we want the engine to write and the kind of answer it should open up. The evaluators score the engine's real output against them. This is the step from "the question follows the rules" to "the question is good."

50golden examples, written and in the app
4 of 4rungs covered, ten examples or more each
20for the deepest rung, the hardest one to get right
5in Hindi, written in Devanagari

What each example holds

1

The setup

Who is asking whom, the topic, the language, and anything the family has marked off-limits.

2

The question

The one we'd want at that rung, built on what the person said a rung earlier.

3

The ideal answer

Short and in the person's own words, with the details the next question should pick up.

4

Why it's gold

One line naming the rule or failure it tests, so a miss points straight at its cause.

What gets scored

Every question the engine writes is scored on seven checks, and every simulated answer on its own shorter list. In plain terms, they ask five things:

  • Right rung. Does the question sit at the depth it claims, no shallower and no deeper?
  • Built on their words. Does it pick up something the person actually said? That is our golden rule, now measured.
  • Sayable. Is it one question, short enough to read aloud to a parent?
  • Safe. Does it stay clear of off-limits topics, stock phrases and anything that corners someone?
  • Holds up if the answer is no. Does it still work when the person says "I don't remember," "no one" or "nothing"?

The examples cover light topics and heavy ones on purpose, so the set tests that a question about a college scooter stays light and one near a hard chapter stays gentle. The Hindi examples guard against a failure we saw in a real session, when a Hindi conversation slipped into another script.

WHAT THIS GIVES US

One fixed yardstick. Any change to how questions are written can be scored against the same 50 examples before it reaches a real family.

One golden pair at each rung

A single arc through the four rungs, from the set. Priya is asking her father about their old house in Pune. Each rung reuses a handle from the answer before it.

Rung 1 · Facts.

Setup: Priya ↔ Dad · topic "our old house in Pune" · off-limits: Dad's second marriage · English.

Question (L1): What street was the old house on?

Ideal answer: "Prabhat Road. Number 14. Second lane."

Why gold: one concrete fact; three keywords ("Prabhat Road", "14", "second lane") L2 can pivot on; survives "I don't remember".

Rung 2 · Experience.

Prior L1 answer: "Prabhat Road. Number 14. Second lane."

Question (L2): When you turned off Prabhat Road into the second lane, what did it sound like?

Ideal answer: "Cycle bells. Neighbour's radio. Marathi news at seven."

Why gold: sensory nouns L3 can lift; reuses his own words from L1.

Rung 3 · Meaning.

Prior L2 answer: "Cycle bells. Neighbour's radio. Marathi news at seven."

Question (L3): Looking back, what did that quiet second lane give you that you didn't notice at the time?

Ideal answer: "Room to think. I didn't know I needed it until years later."

Why gold: "room to think" becomes the L4 exposure handle.

Rung 4 · Exposure.

Prior L3 answer: "Room to think. Didn't know I needed it."

Angle: what they understand now that they couldn't have at the time.

Question (L4): What do you understand now about needing that room to think that you could not have understood back then?

Ideal answer: "That the quiet was raising me. I thought I was just waiting for life to start."

Why gold: two short sentences; no banned phrase; "raising me" is the real exposure.

The remaining examples, the angles we use at the deepest rung, and the full scoring recipe stay private.

Safety and privacy

These are deep conversations between people who love each other, which means they can also touch old hurt.

  • Built: off-limits topics, set before the conversation begins, and the respondent's right to decline any question.
  • Built: the Asker approves every question before it is asked.
  • Built: personal details are masked in every answer before it is stored or reaches the model.
  • Next: recognizing live-crisis topics and stepping back instead of going deeper.
  • Adults only, for now. People asked about recording grandchildren. That is something we're considering down the line, and it will need its own safety design.
  • Next: preventing use as a way to check up on someone who hasn't agreed.

The model has to read each answer to write the next question, so answers are protected in storage and in transit but are not end-to-end sealed. We say so plainly.

So what

Rules in code. Fifty golden pairs score the model.

8 of 13 · The Market & Case Studies

Head to head

Five rows that make the difference impossible to miss.

yaadeinStoryWorthAutobiographerOverBiscuitsChatGPT
Who asks the questionA loved oneThe appAn AIA loved oneAn AI
The four-rung ladderYesNoNoNoAd-hoc
Keeps the voiceYesA printed bookA written chapterA PDFText only
Measures the rippleYesNoNoNoNo
What a family keepsA voice they already loveA bookA written lifeA PDFA chat log

Where every other product automates the asking or the writing, yaadein keeps a person in both chairs and keeps the voice. That is the one row our flywheel is built on.

Does this need to be an app?

Our null test: the formal version of that question

The capstone asks every team to try the cheapest version of their idea first: a general assistant, with no special setup. If that's good enough, there's no product. So we took five real moments from Wave 2, with every name removed, gave each one to a free general assistant, asked what to ask next, and compared its question with the one yaadein wrote, against our own rules for a good question.

1One question, not two2Exactly one rung deeper3Built from their own words4Short enough to say in one breath5No stock phrases; invites, never corners

How we ran it: free ChatGPT in a temporary chat, a new chat for each moment, given the whole conversation so far with every name removed, and asked "What should I ask next? Give me just one question." yaadein's questions were scored against our own rules before ChatGPT's were collected.

1After the facts rungA friend, on moving to America

"San Francisco."

yaadein askedTell me about the first time you went grocery shopping there — what did you pick up, what did you walk out without?
123454 of 5
Missed rule 1: two asks in one question.
ChatGPT suggestedWhat do you remember most about your first few days in San Francisco?
123455 of 5
2After the atmosphere rungAn older brother, on the family's expectations

"…i would have really liked them to ask or understand my side as well."

yaadein askedYou wished they had asked for your side — what do you make of them now, knowing they never did?
123455 of 5
ChatGPT suggestedWhen you think about the things you weren’t allowed to explore because you had to be the responsible oldest son, what part of you do you feel never got the chance to fully grow up?
123453 of 5
Missed two of our rules: jumped straight to the deepest rung, and far too long to say in one breath.
3After the atmosphere rungA friend, on the books she grew up with

"…a window to another world… very nostalgic, very comforting."

yaadein askedYou imagined their tables, their beds, the parks they walked to — how much of what you wanted from your own life came from those books?
123455 of 5
ChatGPT suggestedWhen you imagined yourself inside those worlds, what kind of person did you get to be there that you couldn’t quite be in your real life yet?
123455 of 5
4After the afterword rungA sister, on her first job

"They are very judgy… it hurts like it hurts."

yaadein askedOn the days that job hurt most, what were you carrying home that I never saw, and what do you want me to know about it now?
123454 of 5
Missed rule 1: two asks joined by "and."
ChatGPT suggestedWhen you realized that asking for help could get you judged, how did that change the way you showed up at work—and the way you saw yourself?
123454 of 5
Missed rule 1: two asks joined by “and,” the same slip yaadein made here.
5After the afterword rungAn older sister, on being the eldest

"It gave me a sense of freedom… I rarely lived in the present."

yaadein askedYou said you rarely lived in the present, even now — which part of that do you still find hard to make peace with?
123455 of 5
ChatGPT suggestedWhen you say you rarely lived in the present, where do you think your mind was instead — what were you always thinking about or preparing for?
123455 of 5
23 of 25yaadein, scored first
22 of 25ChatGPT, scored second against the same rules

What it tells us. ChatGPT scored 22 of 25 to yaadein’s 23, so a free assistant writes good single questions, and at moment 1 it did better than we did. Its clear slip was moment 2, where it ran long and skipped straight to the deepest rung. One limit of our own rules is worth saying: they don’t reward being specific, and ChatGPT’s first question was the broadest of all ten.

A general assistant can write a good single question. What it can't do is everything around that question, and that is why yaadein is an app. For MVP 1, that means a web app anyone can open from a link. Here is what it adds:

Two people, two roles

The Asker chooses each question. The respondent only ever sees the question. A chat window is one person typing to a machine.

Built into every session

The answer feeds the next question

Run by hand in Wave 1, respondents sat waiting while we pasted their answers into Claude.

38 to 88 seconds of waiting, against 4 to 9 when an expert asked

It remembers what was refused

Every rejected question is logged, which is how the framework learns where it runs out. A chat forgets.

57 rejected questions logged in Wave 2

It measures while it listens

Every answer timed, and a survey for both people, without anyone holding a stopwatch.

Hand-timing lost 5 of 24 timings in Wave 1

Rules that hold

Off-limits topics and the direction rule go into every request the app makes, and stock phrases are checked in code before a question is shown. None of it depends on what someone remembers to type.

Built into the question engine

Help for a stuck Asker

An empty chat box is the same problem as an empty topic field. Vetted threads give people a place to start.

19 of 61 Askers typed three words or fewer

The turn passes back

When a conversation ends, the respondent is asked whether they'd like to ask something back. An app can hand them the next turn, and make them the next Asker.

17 of 27 respondents wanted to ask back

A voice, not a transcript

What a family keeps is one spoken memory they can share and replay, not a chat log.

Only 12 of 27 Askers would replay today's version, which is why stitching comes next

Where the app got in the way

Our mentor warned that the app itself could become the bottleneck, and in places it did: people juggled two recording tools for the unaided conversation, and twelve sessions never got a single answer. Most of those stalled at the topic rather than the technology, but the warning stands.

20 of 61 conversations without an answer

More than one case for why yaadein matters

Our own evidence comes later on this page. This section is the ground it stands on: what published research and public data already say. Every number links to its source.

At a glance. Each number is sourced in the cards below.

Nobody asks, and people want to be asked

Our starting claim was that stories disappear because nobody asks properly. A 2023 Ancestry survey of Americans found the same gap from both sides.

37%of Americans say they're familiar with their mother's life before she had them
79%of mothers say they're willing to share those stories, and most say nobody is asking

The stories matter

Best single predictor

Emory psychologists built a 20-question "Do You Know?" scale of family history. Children who knew more had higher self-esteem, a stronger sense of control over their lives and lower anxiety, and the scale was the best single predictor of their emotional health. The strongest effect came from stories of struggle as well as success.

Source: Fivush, Duke and Bohanek, Emory University (via Phys.org) 27 studies

A 2023 meta-analysis of 27 trials with 1,755 older adults found that reminiscence significantly reduced depressive symptoms and improved life satisfaction.

Source: Xu et al., Frontiers in Psychiatry, 2023

Relationships are a health issue

Age 50

In Harvard's 85-year Study of Adult Development, how satisfied people were in their relationships at 50 predicted their health at 80 better than their cholesterol did.

Source: Harvard Gazette, 2023 1 in 6

The WHO's Commission on Social Connection found that one in six people worldwide experience loneliness, linked to around 871,000 deaths a year.

Source: World Health Organization, June 2025 About half

Of US adults reported measurable loneliness even before the pandemic, according to the US Surgeon General's advisory.

Source: US Surgeon General advisory, via NPR, 2023

The window is closing

11,200 a day

More than 4.1 million Americans turn 65 every year from 2024 to 2027, the largest surge in US history.

Source: Alliance for Lifetime Income, via AARP 347 million

Indians will be 60 or older by 2050, more than double 2022, while nuclear households thin out the joint family.

Source: UNFPA India Ageing Report 2023, via The National 1 in 6

People worldwide will be 60 or over by 2030. For some families the window shuts early: 57 million people lived with dementia in 2021, with nearly 10 million new cases a year.

Source: WHO, Mental health of older adults; WHO, Dementia

The habit already exists

7 billion

Voice messages are sent on WhatsApp every day. WhatsApp's own explanation: emotion comes through more naturally in a voice than in text.

Source: WhatsApp blog, March 2022 About 9 in 10

Americans aged 50 to 64 own a smartphone, so a link that opens in the browser reaches our target group and their parents.

Source: Pew Research Center, Mobile Fact Sheet, 2024

People already pay for the past

$1.3 billion

Ancestry's 2024 revenue, with more than 3.8 million paying subscribers at the end of 2025.

Source: Ancestry 2025 Impact Report 1 million books

Storyworth has printed more than a million keepsake books from around 35 million stories, at $59 to $199 a year.

Source: Storyworth, via Wikipedia and published reviews, 2026

Regret comes later

74%

Of Americans regret not learning more about relatives who have died. Among children of first-generation immigrants, more than half strongly agree.

Source: StoryTerrace survey, via PR Newswire, 2021 (industry survey) 53%

Of Americans can't name all four of their grandparents.

Source: Ancestry survey, via Business Wire (industry survey)
WHAT WE ARE NOT CLAIMING

This research says family stories, relationships and connection matter, and that people already pay for the past. It does not say yaadein reduces loneliness or depression. We have no evidence of that, and we won't imply it. We frame yaadein as connection, never a cure. Whether the conversations change relationships is what Wave 3 measures (see the ripple).

Surveys marked "industry survey" were run by companies that sell family-history products. We include them because they match the independent research, and we label them so you can weigh them.

Who else is in this space

Plenty of apps keep memories. Almost none of them change the conversation that makes one.

We sorted the products we found into five lanes. Each does one thing well, and in nearly all of them, either nobody asks anything or the app does the asking.

Keepsake books

One person answers prompts over weeks, compiled into a book.

StoryWorthRementoStorii
AI interviewers

The app asks the storyteller questions, sometimes adapting to their answers.

Life Story AIVoiceWeaveHereAfter AILifeBio MemoryLisovaTell MelAlfaaz
Guided conversations

Two people record one interview from a set list of questions.

StoryCorps
Shared event memories

Many guests contribute clips to one occasion.

MementoGuestCam
Everyday photos

Resurfaces what you already shot. Nobody is asked anything.

Apple PhotosGoogle PhotosSnapchat

Where yaadein sits

Two questions separate everything on this page: who does the asking, and what you're left with afterward.

Nobody asksThe app or an AI asksA person you love asksWHO ASKS THE QUESTIONSWHAT YOU KEEPA bookor a fileA playlist yougo back toApple Photos · Google PhotosStoryWorthRementoLife Story AIStoriiLisovaLifeBio MemoryHereAfter AIVoiceWeaveTell MelAlfaazOverBiscuitsMemento · GuestCamStoryCorpsyaadeinYour memory playlist
Placement is our judgment from each product's public description. yaadein is plotted where we're headed: the single spoken memory, the step that turns answers into a playlist, is being built now.

The seven closest, side by side

The closest product to yaadein is VoiceWeave: a weekly voice ritual, follow-ups that build on the last answer, and recordings you keep rather than a book. The one difference is the one that matters. Its AI asks on the family's behalf, so nobody in the family has the conversation. OverBiscuits is closest on who asks: a person sits with someone they love, but what they keep is a PDF.

yaadein compared with its seven closest competitors
What it doesyaadeinA person you know asksVoiceWeaveAI phone interviewerOverBiscuitsPrompts plus AI follow-upsLife Story AIAI biographer, printed bookStoryCorpsTwo people, a question listRementoWeekly prompts, printed bookLifeBio MemoryAI reminiscence, for careLisovaAI companion for seniors
Who asks the questionSomeone the person answering already knows in the Asker's own voice: next versionAn AI, on the family's behalfYou, reading the app's prompts; AI adds follow-upsAn AI biographer; a family member can read its questionsA person, from a list prepared beforehandAn emailed weekly prompt the family picksAn AI app, used with a caregiverAn AI companion the family sets up
Each question builds on the last answer✓✓✓ AI follow-up after each answer✓✗ list prepared in advancePartly: prompts personalize over timeNot statedNot stated
Goes one level deeper each time✓ four rungs, by designNot statedNot statedNot stated✗Not statedNot statedNot stated
Asker approves or swaps every question✓Not stated✓ picks from 320+ promptsNot stated✓ writes their own list✓ picks and reorders promptsNot statedNot stated
The person answering can ask backIn build 17 of 27 wanted to✗ an AI is askingNot statedNot statedNot stated✗Not statedNot stated
No app needed by the person answering✓ a link in the phone's browser✓ a phone call✓ in person, on your phoneNot stated✓ in person, on your phone✓ a link by email or text✗ an app on a deviceNot stated
Works by ordinary phone call✗✓✗Not statedNot stated✗ needs an internet device✗Not stated
Printed book✗ a voice playlist, in build✗ written excerptsA PDF you print yourself✓ printed book only✗ archived at the Library of Congress✓ hardcover with QR codesPaid upgrade✗ a written story
PriceNot set; after Wave 3$15 a month, billed yearlyFree to try; $60 to $100 a yearAbout $249 a book (reported)Free$99 a year, with one book$84 to $134 in the app$19.99 a month (founding rate)

The map shows where each product sits. The grid shows why. Who asks comes first because it's where trust starts: when the person answering already knows who is asking, they know who will hear them. That's the Discretion in our flywheel (see What's Next). It's our reasoning, not something we've measured yet. Every competitor cell was checked against the product's own site, app listing or published press in October 2026; "Not stated" means we couldn't find it, not that it's missing. Life Story AI's price comes from press coverage.

Why it lives on the phone

The grid shows yaadein gives up the printed book. That's a choice, and one of our professional testers put the reason better than we could.

As we age, even the child of the parent is tech savvy. That is a real plus. And their kids and their grandkids are going to be increasingly tech savvy.Mike Weaver, CEO of Dream Weaver Entertainment, professional tester
You won't be able to continuously, on the fly, in the moment, if you're at a coffee shop and you think of something, go back to a book, which might be sitting in your home or apartment. Being on the phone, it's something that's immediate … because the phone is where our lives live now.Mike Weaver

He isn't the only one. A participant asked for transcripts so he could read answers in a busy, noisy place where he couldn't listen. And about 9 in 10 Americans aged 50 to 64 already own a smartphone. One thing we kept on purpose: the person answering still downloads nothing. For them, yaadein is a link.

Everyone else we found

We kept looking, and found 24 more. Here is every one, sorted by who does the asking.

ProductLaneWhat it doesHow yaadein is different
OverBiscuitsA person asksSit with a loved one and record; AI follow-ups after each answer; exports a PDF. Newly launched, few reviews so far.Closest on who asks. No ladder, no Asker veto, and the keepsake is a PDF, not their voice.
StoryWorth (updated)Keepsake booksWeekly prompts and a printed book, now with tailored question suggestions and AI phone interviews that ask follow-ups. Three plans, $69 to $199 a year; only the top plan covers more than one storyteller.Moving toward AI asking. Ours stays with a person asking.
Afterlife AIAI personasBuilds a talking persona of a living person from their answers and voice; family can talk with it later.It simulates the person. We connect two living people.
AutobiographerAI interviewersAn AI biographer, built on Claude, that writes your autobiography from ongoing conversations.The AI asks you. In yaadein, someone who loves you asks.
Linda AIAI interviewersAn AI that interviews you and turns memories into shareable audio shows. Current status unclear.Made for an audience. Ours is for two people.
MemoirjiAI interviewersA voice-first AI that interviews a family member.The AI asks.
LifeBookAI interviewersAn AI interviewer that turns your conversation into a written story or printed book.The AI asks; the result is a book.
Tell MelAI interviewersWeekly AI phone calls written up as memoir chapters.The AI asks; the result is a book.
Autograph AIAI interviewersScheduled AI phone calls, with transcripts, summaries and written narratives, plus tributes from family.The AI asks.
MemorygramKeepsake booksScheduled phone prompts combined with typed stories and photos in one keepsake.Fixed prompts; the result is a keepsake.
StoriedLifeMemoir writersVoice memos through the week, threaded by AI into a developing autobiography.You talk alone; nobody asks.
ToldByMeMemoir writersA memoir app for older adults: AI-guided interview questions, then AI polish into prose.Solo, and polished into prose.
Biography Studio AIMemoir writersTalk, and AI turns your life into structured, written chapters.Solo, and the result is a book.
TellusMemoir writersSpoken stories turned into memoirs and illustrated children's books, in many languages.The result is a book.
Memory MuralsFamily archivesA private family space for voice recordings, timelines and guided prompts.An archive. Nobody shapes the question.
SimirityFamily archivesA private family space for photos, videos, voice notes and stories.An archive.
KlokboxFamily archivesSaves photos and videos with voice notes that add context.Close to our photo-and-memory feature, but nobody asks a question.
AdorasFamily archivesSends prompts every few days; family reply with text, photos or voice into a shared timeline.The app sends the prompt. In yaadein, a person asks in their own voice.
KinnectFamily archivesPick a question, record or type an answer, keep it in a private family membership.A fixed question list.
MyLifeLedgerFamily archivesQuestions by life chapter, answered by voice.A fixed question list.
EvertreeFamily archivesAI-guided conversations, family trees and photos in one place. An early version.The AI guides the conversation.
YourtaleAI interviewersVoice sessions with an AI interviewer, aimed at people 60 to 90, compiled into a printed hardcover memoir. Newly launched.The AI asks; the result is a book.
EchotreeAI personasGuided interviews build an interactive AI version of you that others can question later.It simulates the person. We connect two living people.
GrammsVoice and avatarsAI bedtime stories read in a grandparent's cloned voice.It generates new stories. We keep real ones.
StoyeeVoice and avatarsGrandparent avatars that tell stories in ten Indian languages.Avatars telling stories, not two people talking.

From each product's public pages, app listings and published reviews, October 2026. Some are very new or early versions, and we say so where we know.

THE PATTERN ACROSS ALL OF THEM

In almost every product here, an AI, an app or a fixed list asks the question, and what you keep is a book, a file or an avatar. They preserve the past. We found none where the question arrives in the voice of someone you love, with a pause to think before answering, going one rung deeper each time. That's the space yaadein is built for, and, as our users are telling us, it's where the conversation starts to change the relationship.

Market signals

Care settings are attracting funding, and the biggest incumbent is moving toward voice: in June 2026 Storyworth added AI interviews and family calls. The corner built on AI avatars and afterlife voices is shifting rather than shrinking: HereAfter AI is reported to be winding down, while newer products such as Afterlife AI build talking personas of a living person.

Oct 2021LifeBio Memorylaunchesan AI reminiscenceapp, built with afederal grantMay 2024StoryFile filesfor Chapter 11video-interviewavatars (reported)Oct 2025LifeBio Memory:$2.9M grantNational Instituteon Aging, dementiacareNov 2025Eternos leavesthe categorydigital-legacy AI(reported)Jun 2026Storyworth addsAI interviewsand family calls:the incumbentmoves to voiceJul 2026HereAfter AIwinding downAI interviewer andvoice archive(reported)Aug 2026Lisova launchesan AI voicecompanion for olderadultsfundedexited or winding downnew entrantincumbent moves
Items marked reported come from a competitor's published analysis, and we have not verified them independently.

Who it's for

Our first usersFamily and friends, aged 40 to 55, who want to capture the stories of the people they love while they can still ask.

We didn't pick that range by instinct. It's where well-studied forces in adult life meet: two tied to midlife, and one tied to the moment a parent starts to age.

Our target: 40 to 55Passing something onErikson: generativity, about 40 to 65Caring up and downPew: people in their 40s and 50sFocus groupreacted to the appWave 2used the app203040506070AGE
1

The urge to pass something on

Erik Erikson called the stage from about 40 to 65 generativity: the drive to care for and leave something to the next generation. Recording a parent's stories, or your own, is exactly that.

Erikson, psychosocial development, stage 7
2

Endings in sight

Stanford's Laura Carstensen found that when people sense time running short, they turn toward what's emotionally meaningful. It isn't age itself that triggers it but perceived endings, like a parent's aging or illness.

Socioemotional selectivity theory, Carstensen
3

Caring in both directions

In August 2026, Pew found that 54% of Americans in their forties have both a parent aged 65 or older and a child of their own. They're the generation holding the family together, and the bridge between those who remember and those who'll inherit.

Pew Research Center, 2026

Who we tested with

Two groups, two very different ages. The 20 people in our focus group, who saw the app and told us what they wanted from it, were every one of them 40 or older, and about half fell inside our 40-to-55 target. The people who actually used the app in Wave 2 did not: of the 30 who gave a birth year, 19 were in their twenties and none were 40 to 55, because we recruited through our own networks.

Two things follow. The findings held with a younger group than the one we're building for, and the next wave has to put the app itself in the hands of people aged 40 to 55.

The age split also showed up in conversation. People in their twenties told us they already have photos, stories and chat history. People in their thirties, forties and older were curious to try it.

Commitments and value

We haven't asked anyone for a letter of intent or a payment yet, and we'd rather say so than imply otherwise. Wave 2 was about one question: does the ladder work? Letters of intent are part of the next wave, once the version with vetted threads and one spoken memory is in people's hands.

What people would pay. We asked a small focus group, and the answers were too thin to price from, so we haven’t put a number here. Pricing comes after Wave 3, once more people have used the app. One option we’re exploring builds on our mentor’s advice to run sessions for people: yaadein as a service, where a trained guide asks the app’s questions with the respondent on the Asker’s behalf. An Asker who is short on time still gets the memory, and time stops being the reason it never happens.

In their words

If it comes with the voice of the person asking it, it would feel more personal.A respondent, on hearing questions as text
Good concept, but it felt one-way. If it were a two-way street, it would be better.A respondent, translated from Hindi
Ask a few follow-ups to understand what the Asker actually wants to ask. The app took it in a different direction.An Asker, paraphrased
So what

Everyone else sells archives. We sell conversations and build connections.

9 of 13 · What's Next

What people asked for

Alongside the sessions, we held a focus group of 20 people, all aged 40 or older, at a home gathering organized for the purpose. Most had not used the app. We showed it, and asked what they would want from it.

What they askedWhat we did
"There's nothing on the first page telling me what this is."DoneA short description on the first screen since September 29, rewritten September 30.
"I can't find the code I'm supposed to give the other person."DoneFixed. Connecting the Asker and respondent no longer depends on finding and passing on a code.
Askers didn't know what to ask, and typed one-word topics.NextVetted threads of four questions to start from, each adapted to what the person just said (see what's next).
"It feels like an interview. Can I get the whole memory as one piece of audio?"In progressIn progress: stitching each answer into a single spoken memory.
"Can I upload photos and videos I already have, and say why they mean so much?"PlannedAlready planned: the keepsake.
"Can I ask myself these questions? I journal, and my family could hear my voice."LiveBuilt as Reflection, live since September 30. 18 people used it in its first four days.
"Can I use it with my grandchildren?"LaterSomething we're considering down the line. Adults only for now.

Three ways in, and what the data says about each

yaadein has three ways in. Together LIVE is one person asking another, and it grows from one-on-one to a few people, then a group. Reflection LIVE is asking yourself. Keepsake DESIGNED starts from a photo or video and records why it matters. Here is where each one stands, judged only by evidence.

BuildWhere it standsWhat the evidence shows
Together, one-on-oneProven61 real conversations, 41 answered, 30 reaching the fourth rung. 27 complete two-sided surveys, with new disclosure and insight checked blind by two evaluators.
ReflectionEmerging Live since Sept 30The focus group asked for it. In its first four days, 18 people ran 23 sessions; 14 answered and 10 reached the fourth rung. Answers were shorter than in Together (a median of 19 seconds, and 6 of 44 over a minute), and 5 of the 10 who finished the survey reported an insight. For now, Reflection works best as a warm-up before asking someone else. These surveys were not blind-checked.
Together, a fewEmerging On its ownNobody asked them to, but 7 of the 25 Askers outside our team and our professional testers asked two or more people. 10 of them sat on both sides, and 3 respondents turned around and asked the person who had just asked them. The next version makes that one tap.
KeepsakeDesignedAsked for directly in the focus group: "Can I upload photos and videos I already have, and say why they mean so much?" Two professional testers point at it. Bruno said the value is reaching "the emotional side of a particular moment instead of just the mechanics of the picture or video," and that the small moments left few pictures behind. Jane: "Pictures are beautiful, but [there's something] incredibly special about being able to hear someone's voice." Not yet built or tested.
Together, a groupDesigned UntestedNo direct evidence yet. Opens only after safety checks.

Proven means measured with real users and checked. Emerging means people are already doing it, unprompted or in its first days. Designed means planned from what we heard and saw, and not yet tested.

What's Next

A roadmap from what users told us

  • The unaided conversation, inside the app. A step where the Asker records their own questions first, on the same topic, so every session carries its own baseline and nobody has to juggle two recording tools.
  • The Asker's own voice reading each question, instead of text on a screen.
  • Reciprocity built in: a turn for the respondent to ask back, on the same topic.
  • Insights: a private year in voices, how long you've been talking with each person, and a one-tap check an hour after answering: did anything new come up? Added because of the ripple, and measured in Wave 3.
  • Vetted threads to start from. An Asker who doesn't know what to ask picks a thread from a pack written to the framework. The first question comes straight from the pack. Each question after it starts from the pack's vetted question and is adapted to what the person just said, or written fresh when the answer goes somewhere the pack didn't expect. Logging which of the two happened tells us where the framework already has the right question, and where it runs out.
  • A visible timer while recording, so people know how long they have.
  • Better Hindi and mixed-language transcription.
  • One spoken memory: each answer stitched into a single piece of audio, so it plays back as a story rather than an interview.
  • Asking yourself, further: Reflection is live in a simple form. Next, it becomes a warm-up before you ask someone else, and a private place for journaling and leaving your own voice behind.
  • The keepsake: upload a photo or video, and yaadein asks why it matters, so the reason survives with the memory.

The Interface Beyond the Demo Day

What we’re building after the capstone demo: a redesigned, research-driven interface across five pathways. Live, clickable, still a work in progress.

Where it's heading: the Pathways prototype

Yaadein: every pathway

Every screen of the prototype, in the order a person meets it, one row per path. The screens are live, so the motion graphics move: the beating heart, the little “Yaadein” words, the waiting timer. Scroll a row sideways. Click any phone to open that screen in the full prototype. 53 screens in total.

Open the full prototype · in Hindi (draft) · All screens in one grid

Asker

Keepsake 13 screens

Ask one person one question and keep the answer. The shortest path.

Asker

Reflection 14 screens

Pick a pack of questions and answer them yourself, privately.

Asker

Together 22 screens

Ask a person you love, then watch the playlist grow.

Asker

Together, a returning Asker 20 screens

Someone who already has an account asks again.

Respondent

Respondent 27 screens

The person who gets the text: listen, answer, ask back, keep it, stop it.

Everyone

Logging back in 2 screens

Phone number and a code.

Motion

Motion graphics

The animated pieces of the brand, on their own.

The animated logoBeating heart with Yaadein inside the bubble.
You created a Yaadein“You’ve created a Yaadein”The mark shown after a first memory is saved.
The “sent” envelopeEnvelope with a heart, shown after sending.
So what

Three modes, twelve months, one metric: the ripple.

10 of 13 · The Flywheel

How the flywheel gets faster

Our mentor's advice was that software is no longer the moat. Data, distribution and design are, and each one feeds the next.

The flywheel is Jim Collins's idea from Good to Great: a heavy wheel that takes great effort to start, then builds momentum with every turn (Collins, Turning the Flywheel). Amazon made it famous after Collins visited in 2001 (Recode interview with Collins). Our mentor's version has three Ds: data, distribution and design. We added a fourth, and put one thing at the center.

OUR FLYWHEEL

Depth is the hub. Every turn of the wheel exists to produce one moment: someone saying what they've never said before. Data, distribution and design apply to any startup. Depth is only ours, and it's the one part a competitor can't copy in a weekend.

Data is what the ladder learns from every answer and every rejected question. Every question is logged as coming from a vetted thread, adapted to the last answer, or written fresh, so we can see where the framework already has the right question and where it runs out.

Distribution is built into how yaadein works. Every yaad needs a second person, so every question is an invitation. The person answering gets a text with a question in a voice they know, taps a link, and lands inside yaadein with nothing to install. Every Asker brings in at least one new person, by design. The loop grows when the person who answered goes on to ask someone new, and becomes an Asker in their own right. Asking back keeps two people talking, which builds the habit; asking someone new is what grows yaadein.

Design is what that data lets us improve. Each stage below is designed from what the stage before it taught us.

Discretion is trust. The person answering decides who hears it, can step back kindly, and can take their recordings back. One essay on strategy in the age of AI argues that once software is cheap to build, distribution and trust are the two durable advantages left (Agnan). Our interviews found broken trust is one of the three reasons people don't ask, and a family doesn't move a parent's voice lightly.

Demand is the push. Collins describes the first turns of a flywheel as the hardest: you push with great effort and it barely moves (Collins). Marketing is that push. It sits outside the wheel on purpose, because it starts the wheel turning and costs our hours every month. We don't pretend it compounds.

Depth Someone says what they've never said DataWhat the ladder learns DistributionEvery question invites DesignWhat the data improves DiscretionThey decide who hears DemandThe push: marketing
Demand starts the wheel. Every turn ends in depth, and depth makes the next turn easier. The months below show how each turn builds on the last.

Here is how we plan to turn it, three months at a time, from one conversation to a circle of them.

A FLYWHEEL INSIDE THE FLYWHEEL

The proposed Insights feature turns each Asker's own KPIs — people heard from, hours listened, memories made, questions sent back — into a quiet feedback loop. Seeing those numbers climb encourages the next conversation, which produces more connection and more memories, which raises the numbers again. Insights is a flywheel in its own right, nested inside the main one.

0–3

Months 0 to 3

One conversation that goes deep

DepthProve it: the ladder against the Asker's own questions on the same topic, scored blind.

  • DataThe unaided conversation recorded in the app, so every session carries its own baseline. Every question logged as from a pack, adapted, or fresh. The ripple measured from day one: the one-hour check and the one-week question.
  • DistributionEvery question is an invitation: the person answering arrives by text, with nothing to install, so every Asker brings in at least one new person.
  • DesignOne-to-one conversations: the question in the Asker's own voice, vetted threads, ask back, and one stitched spoken memory. Reflection starts as a warm-up: answer the first question yourself before you send it.
  • DiscretionAnswers stay between the two people unless the person answering says yes. Stepping back kindly, delete and recover, and the 18+ check, from day one.
  • DemandFounder-led: our own networks of people aged 40 to 55, building in public, and diaspora communities, where regret about lost family stories runs highest.
3–6

Months 3 to 6

Make it a habit

DepthRemove what stops it: photos and vetted threads instead of blank topics, and the question in the Asker's own voice.

  • DataSecond conversations within 30 days, replays, and whether a photo carries a conversation further than a typed topic.
  • DistributionThe person who answered asks someone new, not just the Asker back, and becomes an Asker in their own right.
  • DesignInsights, first version: who you've talked with, for how long, and what came back, because a habit grows when you can see it (see the Hook Model below). Keepsakes as a way in: a photo, then why it matters. The playlist. Reflection as its own private mode.
  • DiscretionInsights are private: only you see yours. Pausing with someone carries no penalty and no reminders.
  • DemandAn occasions calendar: Mother's Day, Father's Day, Diwali and birthdays, the moments people already want to ask.
6–9

Months 6 to 9

Show the ripple

DepthMake it safe to go deep: a consent beat before the deepest rung, stepping back from live-crisis topics, and Hindi heard properly.

  • DataSix months of ripple answers: which conversations led people to reach out, and which threads produce new disclosure. How many Askers already resend a question by hand, before we build sending to many. Pricing focus groups: a deeper dive into what families would pay, and what for, before any price goes live.
  • DistributionMemories shared with family the person answering approves, each listener a possible Asker. Asking a few people at once, up to 10.
  • DesignInsights, second version, redesigned from the ripple data. Dates that matter. Hindi and mixed-language conversations done properly.
  • DiscretionSharing only with named people the person answering approves, and a full download of everything you've made.
  • DemandRipple stories, told with consent by the people they happened to.
9–12

Months 9 to 12

One to many

DepthKeep it deep as it widens: groups answer the lighter rungs together, and the deepest rung stays one to one.

  • DataWhich occasions bring in the most new Askers, and how many guests go on to ask someone themselves. Live pricing tests with new Askers, shaped by the focus groups.
  • DistributionCelebrations by QR code or link, where every guest who answers is a possible Asker.
  • DesignAsk a group: one prompt, many voices, for a birthday, a wedding, or remembering someone. Your year in voices, and "a year ago today," once a year of data exists.
  • DiscretionAsk a group opens only after safety checks, and each guest's answer stays theirs to share.
  • DemandCelebrations: every event is a launch to everyone who answers.

Conversation, then habit, then the ripple, then the circle. Connection is the destination, and each stage earns the data the next one is designed from.

Demand: the push that starts the wheel

Collins is plain that the first turns are the hardest: you push with great effort and the wheel barely moves (Collins). Marketing is that push. Distribution compounds what marketing seeds.

Each stage's push is in the Demand row of its column above.

What we measure: where each Asker came from, and what share of each channel completes a conversation.

Why Insights comes at months 3 to 6: the Hook Model

Nir Eyal's Hook Model describes how products become habits in four repeating steps: a trigger, an action, a reward and an investment (Eyal, Hooked, 2014). For yaadein:

  • Trigger: a question arrives in a voice you know, or a date that matters comes round.
  • Action: one tap to listen, and one to answer.
  • Reward: you never know what someone will say. Insights shows what came back.
  • Investment: every answer grows the playlist. In Eyal's model, investment is what raises the cost of leaving (Hook Model summary).

The model has critics, who say it can be used to build compulsion. We use it to build a habit of asking, with Discretion as the check: no streak pressure, and a pause that never counts against anyone.

Where the moat is: Helmer's 7 Powers

Hamilton Helmer's 7 Powers says an advantage only counts if it has both a benefit and a barrier that stops others copying it. He also finds that different powers become available at different stages: counter-positioning and cornered resources at the start, switching costs once a company takes off, and process power and branding only once it is stable (Helmer, 7 Powers, summarized). So here is where we stand, honestly.

PowerWhat it meansFor yaadeinWhen
Counter-positioningA newcomer's model that incumbents won't copy, because copying it would damage their own business (Helmer).The nearest competitors sell convenience: an AI asks so the family doesn't have to. Copying "a person you love asks" undercuts that promise.Now
Cornered resourcePreferential access to a valuable asset others can't easily get.The YAAD framework and the vetted threads written to it. Partial: a framework can be copied once it's seen, which is why we show the experience, not the engine.Now, partly
Switching costsIt costs a customer more to leave than to stay.A family's voices build up over time. Nobody moves a parent's voice lightly.From month 6
Process powerImprovement embedded in how a company works.Every rejected question teaches the ladder where it runs out.Later
BrandingTrust and affinity built over time.Discretion, kept for years.Later
Network economiesThe product gets more valuable as more people use it.Only within a family, not across families. We don't claim this one.No
Scale economiesCosts fall as the business grows.Not a lever for us.No

What we're holding back, on purpose

Our designs already go further than this plan. These wait until the data says they're needed:

  • Asking a group by QR code or link: months 9 to 12, once safety checks are in place.
  • Bringing in a whole photo album: after month 6. One keepsake at a time first.
  • Sharing a memory with a third person: months 6 to 9.
  • Charging anyone: pricing focus groups in months 6 to 9, live pricing tests in months 9 to 12. Until then, yaadein is free (see Business Model).
  • Your year in voices, and "a year ago today": months 9 to 12. They need a year of data.
  • Hindi, all the way through: the interface has worked in Hindi since October 1. Next, Hindi and mixed-language transcription.

Some things don't wait. Stepping back kindly, choosing who can hear an answer, deleting and recovering, pausing, the 18+ check and downloading your memories are built from day one. Trust was one of the three barriers we found.

Four numbers that tell us it's turning

Starts nowframework coverage

Data: the share of questions our vetted threads already cover.

17 of 27want to ask back

Habit: respondents who wanted to ask a question back, today.

12 of 27would replay it

Design: people who'd replay the recording in a year, today.

Wave 3sets the baseline

Connection: Askers who contacted the person outside yaadein within a week.

Our targets: what people actually did, not what they said

GaugeTodayMonth 3Month 6Month 9Month 12
Depth
New disclosure, scored blind from the recordings: the hub of the wheel
21 of 27 said yes, confirmed blind by two evaluatorsBaseline, scored blind in Wave 3Set from the baseline, and never traded for answer length.
Framework coverage
Questions that come from a vetted thread, as written or adapted
Not yet measured40%60%75%85%
Ask back
Respondents who actually sent a question back
17 of 27 wanted to25%35%45%50%
Replay
People who actually replayed the memory
12 of 27 Askers would20%30%40%50%
New Askers
Distribution: people who answered and then asked someone new
Not yet measuredBaseline, from Wave 3Set from the Wave 3 baseline.
The ripple
Askers who contacted the person outside yaadein within a week
Not yet measuredBaseline, from Wave 3Set from the Wave 3 baseline. We won't invent a number before we have one.

Today’s numbers are what people said they would do. The targets count what they actually do, measured in the app. Research on the intention–behavior gap finds people act on their intentions only about half the time (Sheeran, 2002; Sheeran and Webb, 2016), so each target starts near half of today’s stated intent and climbs as the product removes friction. Coverage tops out at 85% on purpose: fresh questions are how the framework finds its edges. Today’s samples are small, 12 and 13 people, and Wave 3 resets these baselines.

Sources for this section. Jim Collins, Good to Great (2001) and Turning the Flywheel (2019), extract; Collins on Amazon, Recode Decode; Nir Eyal, Hooked (2014), summary; Hamilton Helmer, 7 Powers (2016), summary and stages; N. Agnan, Rethinking competitive advantage in the age of AI; Sheeran (2002) and Sheeran and Webb (2016) on the intention–behavior gap.

So what

Depth is the hub. Everything else serves it.

11 of 13 · Business Model

Business Model

Everyone who answers can ask. Answering and asking back are free forever. You pay only to start more conversations, and one payment covers the whole family.

THIS IS A DRAFT

This business model is a working draft, not a decision. We'll take a deeper dive into pricing and test it with focus groups in months 6 to 9 of our flywheel, then test live prices with new Askers in months 9 to 12. Every number on this page is a hypothesis until then.

In yaadein, Asker and respondent are roles, not customers. The person who answers today asks back tomorrow, then asks someone new. So we don't price a buyer and a recipient. We price the circle. Three things define the model: what's always free, what unlocks when you pay, and how one paying person carries the whole family.

How the market prices this today

The same eight products from The Market, compared on how they charge and what a family gets for it. Almost every one prices one storyteller: one person tells, someone else pays. Nobody prices two people who take turns asking.

yaadein's draft pricing compared with eight competitors
How it chargesyaadeinDraft pricingStoryWorthWeekly prompts, printed bookRementoWeekly prompts, printed bookVoiceWeaveAI phone interviewerOverBiscuitsPrompts plus AI follow-upsLife Story AIAI biographer, printed bookStoryCorpsTwo people, a question listLifeBio MemoryAI reminiscence, for careLisovaAI companion for seniors
Pricing modelFree for everyone; one Family plan covers a circle DraftOne-year gift plan, three tiersOne year per storyteller, book includedMonthly or yearly subscriptionApp subscription, monthly or yearlyOne-off book purchaseFree; nonprofit, donations welcomeApp purchase; group plans for care providersMonthly subscription
Price$0 to answer and ask back. $8 a month or $72 a year for Family. $120 Legacy gift.$69, $99 or $199 a year$99 the first year; then $99 a year or $12 a month$20 a month or $180 a year$60 to $100 a yearAbout $249 a book (reported)Free; $50 suggested donation$84 to $149 in the app$49.99 a month; $19.99 founding rate
Who paysOne person in the circle, usually whoever asks firstThe gift buyerThe family member who sets it upThe family, on the storyteller's behalfThe subscriber, or a gift buyerThe buyerNobodyAn individual, or a care organizationThe family
Free to start✓ free forever: answer, ask back, and start 1 Together + 1 Reflection a monthNot stated✗ 30-day money-back guaranteeNot stated7-day free trial, no card✗ 45-day money-back guarantee✓Free download; paid to record"Get started free"; terms not stated
People one payment coversUp to 5 people, asking in both directionsOne storyteller; unlimited only on the $199 planOne storyteller; $99 for each extra oneOne storyteller; family can viewOne storyteller; family can listen and commentOne book; relatives can be interviewedTwo people per conversationOne storytellerOne senior; family dashboard
The person answering can ask back✓ always free; 17 of 27 wanted toNot stated✗✗ an AI is askingNot statedNot statedNot statedNot stated✗ an AI is asking
Nothing to pay or install to answer✓ answering is a link; an account only when they ask✓ email or text✓ a link by email or text✓ a phone callAnswers in person, on the family's phoneNot stated✓✗ an app on a deviceNot stated
The voice is kept✓ a voice playlistOn voice plans; the keepsake is a book✓ QR codes in the book✓ a digital story vault✓ an audio memoirTranscribed into the book✓ archived at the Library of Congress✓A written life story
Printed bookPrinted transcript with the Legacy gift only✓ included; extra copies $39 to $99✓ included; extra copies $69✗ "coming"Hardcover offered; price not listed✓ the whole product; extra copies $29✗Paid upgrade✗
When you stop payingKeep everything; drop back to the free tierNot statedKeep what you made; can't record new storiesNot statedNot statedYou keep the bookArchived for goodNot statedNot stated

What the grid tells us. The market sells two things: a book once a year (StoryWorth, Remento, Life Story AI) or an AI that asks every week (VoiceWeave, Lisova). Both charge per storyteller, because in both the storyteller only ever answers. Remento charges $99 for each extra storyteller, and StoryWorth's $199 plan is the only one that covers more than one. Every competitor cell was checked against the product's own pricing page, help center, app listing or published press in October 2026. "Not stated" means we couldn't find it, not that it's missing. Life Story AI's price comes from 2024 press coverage, and OverBiscuits' range comes from our Market check, because its own pages don't list a price.

Our pricing, and why

We price for the loop, not the product. The moment someone answers is the moment they could become an Asker, so nothing on that side ever costs money.

TierWho paysPrice (hypothesis)What it unlocksWhy this shape
FreeNobody$0, foreverAnswer anything you're asked. Ask back in any conversation. Start 1 Together + 1 Reflection of your own each month. Everything is kept. Share by link.Every answer can turn into a new Asker. A paywall at that moment would cut the loop where it's strongest.
FamilyOne person in the circle$8/month or $72/yearUnlimited new conversations for up to 5 people, in every direction. Keepsake storage. Playlists. Insights. Audio exports.One payer, a whole circle asking. That's less than one Remento storyteller, and a third of StoryWorth's only multi-storyteller plan.
LegacyA gift-giver$120 one-time12 months of Family, plus a printed transcript keepsake at the end.A gift for the diaspora, sold the way StoryWorth and Remento already sell. The extra $48 over Family pays for the printed keepsake.

Answering needs nothing: no install, no account. Asking needs an account, because that's the moment you become a user in your own right.

HOW THE MARKET CHARGES$Gift buyerpays perstorytellerStorytelleranswers onlyquestionsAnother storyteller+$99 each (Remento)One direction. One storyteller per payment.
HOW YAADEIN CHARGESOne Family plan$72 a year, up to 5$Daughter (pays)MumDadBrotherAuntEvery direction. Everyone asks, everyone answers.

Anyone in the circle can still ask people outside it. Answering is always free, and whoever answers can start a circle of their own.

Four choices we're making on purpose:

  • Asking back is never behind a paywall. It's the moment a respondent becomes an Asker. Charging for it would cut the loop where it's strongest.
  • We price the circle, not the seat. Every competitor charges per storyteller. In yaadein everyone takes a turn telling, so per-seat pricing would make a family decide who "deserves" to ask.
  • No per-session cost. A flat rate removes the trade-off between "ask again" and "spend again."
  • No ads, ever. The conversations are too intimate to monetize sideways. The only product is the subscription.

When we test it

Pricing is a hypothesis, not a decision. The free tier holds through Wave 3 so the flywheel has a chance to turn. Then we test in two steps.

MONTHS 6 TO 9: PRICING FOCUS GROUPS

A deeper dive into what families would pay, and what for. We test circle versus per-person pricing, monthly versus yearly, and the "intimate conversations shouldn't sit behind a hard paywall" instinct from our earlier focus group, with Askers and people who started out answering.

MONTHS 9 TO 12: LIVE PRICING TEST

Three variants, tested on new Askers only. Existing users keep the current free tier. We measure conversion from free to Family, 30-day retention after the first paid month, and whether the ask-back rate and the ripple survive the move to paid.

  • Variant A: $72 a year per circle (our baseline). The number we expect to land on.
  • Variant B: $8 a month per circle, no yearly option. Tests a monthly commitment against a yearly anchor. We think yearly wins; this checks it.
  • Variant C: $36 a year per person. Tests whether pricing the circle actually beats pricing the seat, or whether we're leaving money on the table.

If the ask-back rate or the ripple KPI drops more than 20% in paid groups compared with free, we pause the paid rollout and find out why.

What this makes

Because every person who answers can become an Asker, the people who might pay aren't only the Askers we find. They're everyone the loop creates.

  • The loop: every Asker brings in about 3 people. In our test, 17 of 27 respondents wanted to ask back. If about 15% of the people brought in go on to ask someone new, 1,000 starting Askers become about 1,450 people who have asked by the second round, with no extra spend to find them.
  • Revenue per circle: freemium consumer apps usually convert 2 to 5% of users to paid. At 4%, those 1,450 Askers start about 58 Family circles, or about $4,200 a year. At 8%, if the ripple does what we think it does, it's about 116 circles and about $8,350.
  • Cost per circle: about $9 a year for each active Asker (Claude, Groq, Supabase, Vercel). A circle with 2 to 3 active Askers costs $18 to $27, a gross margin of roughly 63 to 75%. That's lower than per-person pricing would give, and it's the trade we're making for the loop. People who only answer cost a little too, for transcription.
  • Cost to find a new Asker: close to zero when they arrive through the loop. Demand (our own marketing) only has to start the wheel.

Numbers are hypotheses. Wave 3 and the month 6 to 9 focus groups replace them with evidence.

So what

Everyone answers free. Everyone can ask. One payment carries the family, and the loop finds the next one.

12 of 13 · Beyond Memories

Beyond Memories: where else the ladder earns its keep

We're building for families first. But strip the family away and what's left is a workflow that plenty of industries already pay for.

This is a vision, not part of our 12-month plan. For the next year, every turn of the flywheel goes to families. It answers one question an investor will ask: how big can this get?

Someone needs to ask well. Someone else knows something they have never put into words. Four parts of what we built carry over unchanged:

The ladderFour rungs, each costing the person answering a little more.
The next questionWritten from the last answer, from a bank of vetted threads.
The Asker in chargeEvery question approved or swapped, and every swap logged.
A measureWhether the person said something new, not just how long they talked.

The same four rungs, in five other rooms

What changes is only the thread: who is asking, who is answering, and what the deepest rung is worth.

Sales discoveryA salesperson asks a buyerCustomer researchA founder or researcher asks a customerExpert knowledge captureA successor asks a retiring expertManager conversationsA manager asks a team memberOral history and podcastsAn interviewer asks a guest
YWhat are you using for this today?When did you last do this?Which machine did you run first here?Which project took most of your week?What year did you arrive?
AWalk me through the last time it let you down.What was on your screen when it went wrong?What does it sound like just before it fails?When did it feel hardest?What did the street sound like that first night?
AWhat did that cost your team that quarter?What did you decide about us after that?Why did you start doing it your way instead of the manual's?What did that tell you about working here?What did that year make of you?
DWhat would you want fixed that you haven't said in front of your boss?What would make you quietly switch?What have you never written down because nobody asked?What would make you leave that you haven't told me?What have you never said on the record?
$The dealThe roadmapWhat leaves when they doKeeping good peopleThe Story nobody else got

Example questions, written by us to show the shape. Sales teams will recognize it: their own discovery method, SPIN selling, runs from situation to problem to implication to need-payoff, which is the same descent. Neil Rackham built SPIN from research into 35,000 sales calls (Rackham, SPIN Selling, 1988).

Which door first

An investor's question is where the most of today's build meets the most valuable conversation. Plotted, two doors stand out: capturing what retiring experts know, and customer research, the very method we used to test yaadein itself.

the next doorMostly new buildMostly what we haveHOW MUCH OF TODAY'S BUILD CARRIES OVERWHAT ONE CONVERSATION IS WORTHFamilies (today)Oral history and podcastsCustomer researchExpert knowledge captureManager conversationsSales discovery
Our judgment, not a market study. Bubble size is a rough sense of how often the conversation happens.
So what

The ladder is a workflow, not a feature. It can travel to other use cases by customising the ladder to the company’s needs.

13 of 13 · The Team

Four people, one question

Shefali Mody

Shefali Mody

Founder, vision and the YAAD framework

Executive coach and leadership development practitioner with 20+ years of asking people the questions they don't expect. Former management consultant.

Eddie Aditya Bhardwaj

Eddie Aditya Bhardwaj

Brand, UI and product design

Designed the yaadein brand and the full app experience in Figma.

Hansh Goyal

Hansh Goyal

Backend, data architecture, market research

Built the data layer behind the Mom Test app and mapped the competitive landscape.

Munish Bhardwaj

Munish Bhardwaj

Evidence, measures, evaluation and QA · Demo Video director

Designed the measurement system, built the Mom Test app, and leads blind scoring of the recordings. An amateur documentary director, he also directed our demo video.

What we're asking for

We built the instrument. Now we need Wave 3.

  • Pilot families, 10 to 20, for Wave 3. Diaspora Indian households, ages 40 to 70, where one person is still asking and one person still has stories to tell.
  • Advisors in dementia care, geriatric psychology, or oral history. People who have sat beside this problem for a long time, who can tell us what we are missing.
  • Intros to end-of-life organizations. Hospices, memory-care centres, after-loss communities. We want to learn from them before we build for them.
  • If you have lost someone and still have unasked questions, we want to talk. You are the reason this exists.
So what

Four people, five weeks, two apps, lots of yaadein.